
Apache Spark Error: Not Found: Value sqlContext

I Am Trying to Set up Spark in Windows 10. Initially, I Faced This Error While Starting and the Solution in the Link Helped. Now I Am Still Not Able to Run...
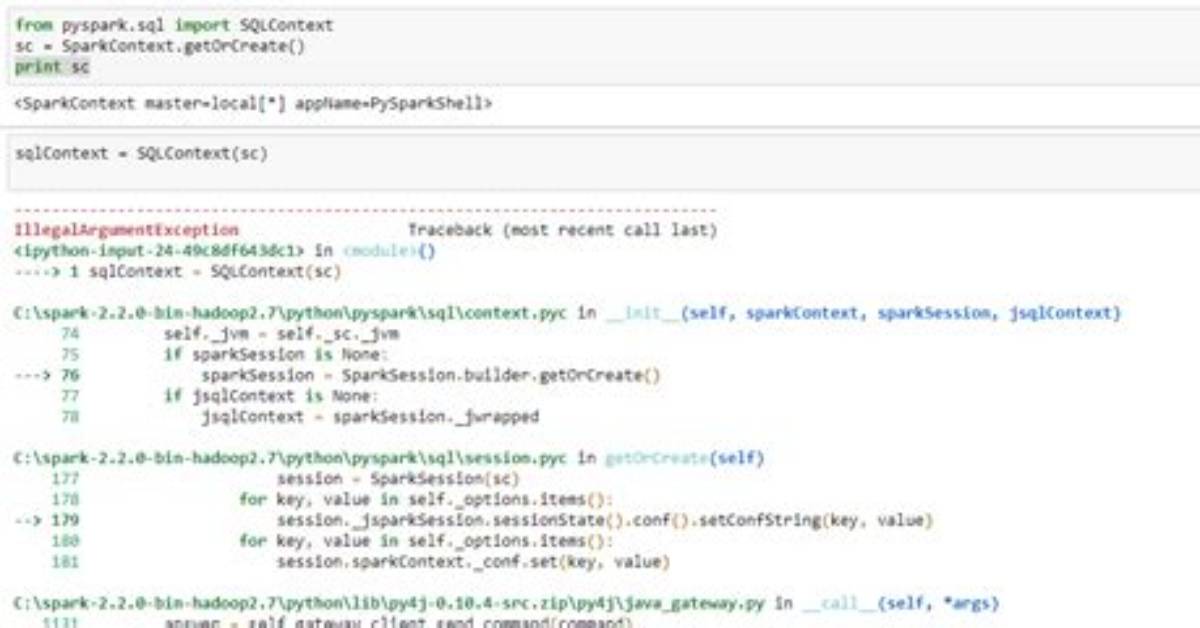
I am trying to set up spark in Windows 10. Initially, I faced this error while starting and the solution in the link helped. Now I am still not able to run import sqlContext.sql as it still throws me an error
----------------------------------------------------------------
Fri Mar 24 12:07:05 IST 2017:
Booting Derby version The Apache Software Foundation - Apache Derby - 10.12.1.1 - (1704137): instance a816c00e-015a-ff08-6530-00000ac1cba8
on database directory C:\metastore_db with class loader org.apache.spark.sql.hive.client.IsolatedClientLoader$$anon$1@37606fee
Loaded from file:/F:/Soft/spark/spark-2.1.0-bin-hadoop2.7/bin/../jars/derby-10.12.1.1.jar
java.vendor=Oracle Corporation
java.runtime.version=1.8.0_101-b13
user.dir=C:\
os.name=Windows 10
os.arch=amd64
os.version=10.0
derby.system.home=null
Database Class Loader started - derby.database.classpath=''
17/03/24 12:07:09 WARN ObjectStore: Failed to get database global_temp, returning NoSuchObjectException
Spark context Web UI available at
Spark context available as 'sc' (master = local[*], app id = local-1490337421381).
Spark session available as 'spark'.
Welcome to
      ____              __
     / __/__  ___ _____/ /__
    _\ \/ _ \/ _ `/ __/  '_/
   /___/ .__/\_,_/_/ /_/\_\   version 2.1.0
      /_/

Using Scala version 2.11.8 (Java HotSpot(TM) 64-Bit Server VM, Java 1.8.0_101)
Type in expressions to have them evaluated.
Type :help for more information.

scala> import sqlContext.sql
<console>:23: error: not found: value sqlContext
       import sqlContext.sql
              ^
5 Answers
Spark context available as 'sc' (master = local[*], app id = local-1490337421381).
Spark session available as 'spark'.
In Spark 2.0.x, the entry point of Spark is SparkSession and that is available in Spark shell as spark, so try this way:
spark.sqlContext.sql(...)
You can also create your Spark Context like this
val sqlContext = new org.apache.spark.sql.SQLContext(sc)
First option is my choice as Spark shell has already created one for you, so make use of it.
Since you are using Spark 2.1 you'll have to use the SparkSession object. You can get a reference to SparkContext from the SparkSession object
var sSession = org.apache.spark.sql.SparkSession.getOrCreate();
var sContext = sSession.sparkContext;
If you are on Cloudera and have this issue, the solution from this Github ticket worked for me ():
The root user (who you're running as when you start spark-shell) has no user directory in HDFS. If you create one (sudo -u hdfs hdfs dfs -mkdir /user/root followed by sudo -u hdfs dfs -chown root:root /user/root), this should be fixed.
I.e. create a user home directory for the user running spark-shell. This fixed it for me.
And don't forget to import the context!
import org.apache.spark.sql.{SparkSession, types}
You have to create sqlContext in order to access it to execute SQL statements. In Spark 2.0, you can create SQLContext easily using SparkSession like below.
val sqlContext = spark.sqlContext
sqlContext.sql("SELECT * FROM sometable")
Alternatively, you could also execute SQL statements using SparkSession like below.
spark.sql("SELECT * FROM sometable")
Robert Thorne covers electric vehicle innovations, autonomous driving systems, global mobility trends, and automotive engineering developments.
