
Ascii vs Unicode + Utf-8

Was Reading Joel Spolsky's 'The Absolute Minimum' About Character Encoding. It Is My Understanding That Ascii Is a Code-Point + Encoding Scheme, and in Modern...
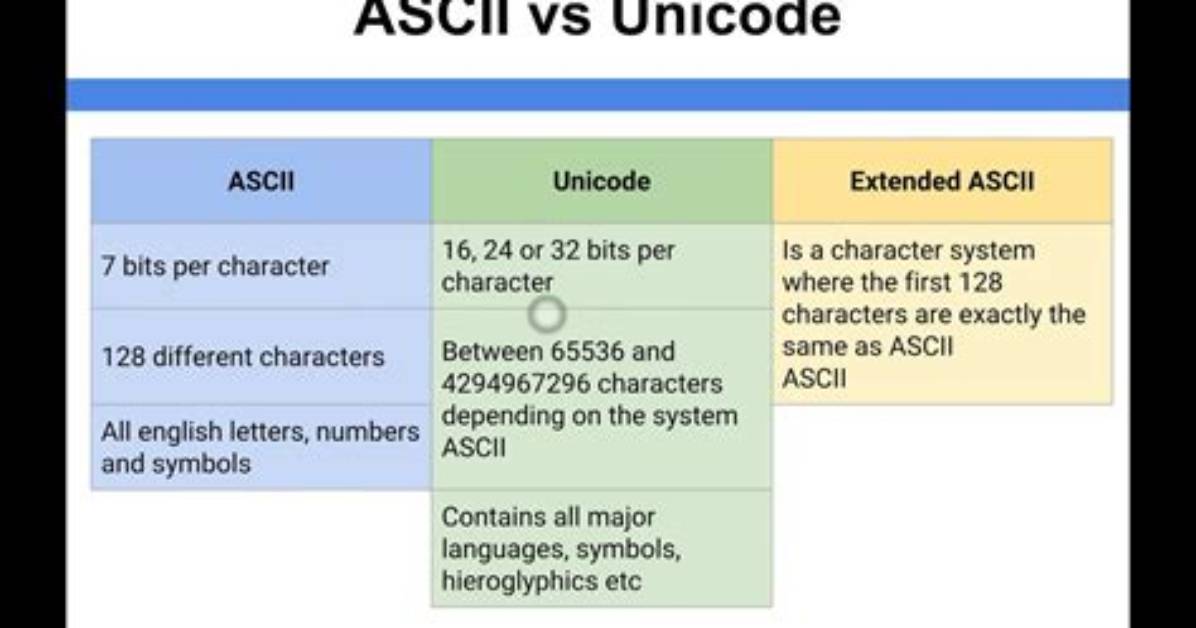
Was reading Joel Spolsky's 'The Absolute Minimum' about character encoding. It is my understanding that ASCII is a Code-point + Encoding scheme, and in modern times, we use Unicode as the Code-point scheme and UTF-8 as the Encoding scheme. Is this correct?
2 Answers
In modern times, ASCII is now a subset of UTF-8, not its own scheme. UTF-8 is backwards compatible with ASCII.
Yes, except that UTF-8 is an encoding scheme. Other encoding schemes include UTF-16 (with two different byte orders) and UTF-32. (For some confusion, a UTF-16 scheme is called “Unicode” in Microsoft software.)
And, to be exact, the American National Standard that defines ASCII specifies a collection of characters and their coding as 7-bit quantities, without specifying a particular transfer encoding in terms of bytes. In the past, it was used in different ways, e.g. so that five ASCII characters were packed into one 36-bit storage unit or so that 8-bit bytes used the extra bytes for checking purposes (parity bit) or for transfer control. But nowadays ASCII is used so that one ASCII character is encoded as one 8-bit byte with the first bit set to zero. This is the de facto standard encoding scheme and implied in a large number of specifications, but strictly speaking not part of the ASCII standard.
Elena Rostova holds a Master's degree in Public Health Journalism. She covers groundbreaking medical research, holistic wellness trends, mental health awareness, and nutritional science.
