
C Lexer, Understanding Documentation, Preprocessing Tokens

My Goal Is to Build a Parser for a Reasonable Subset C and Right Now I'm at the Start, Implementing the Lexer. Answers to a Similar Question on the Same Topic...
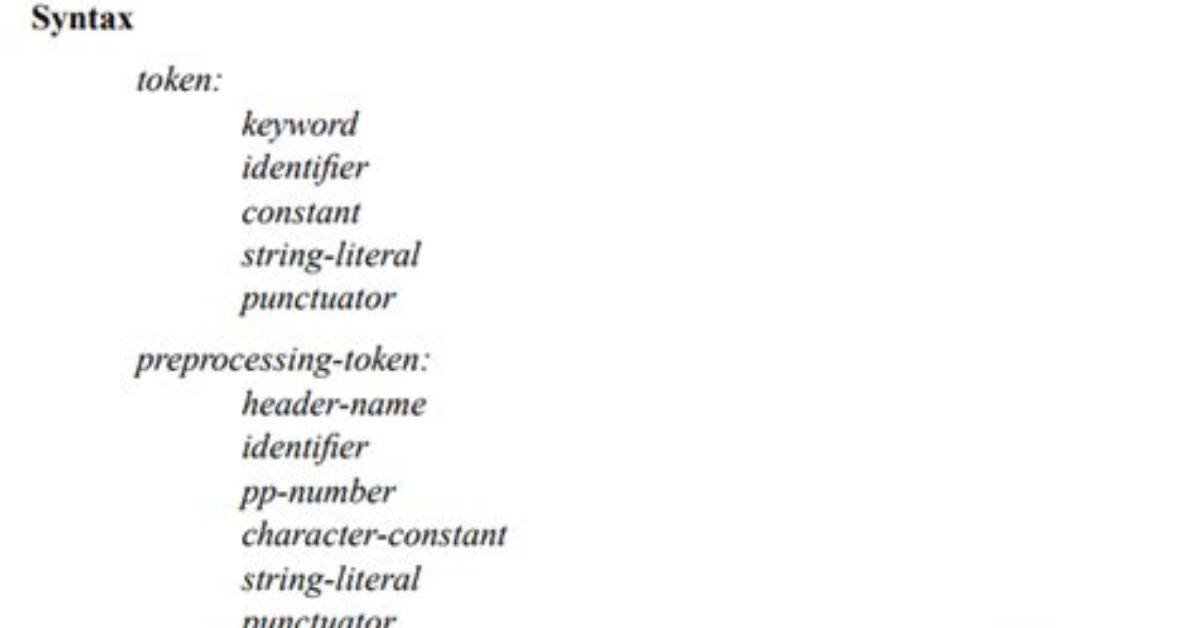
My goal is to build a parser for a reasonable subset C and right now I'm at the start, implementing the lexer. Answers to a similar question on the same topic pointed towards the International Standard for C (700 pages of documentation) and the Yacc grammar webpage.
I would welcome any help with understanding the documentation: Is it true that the following picture from the documentation represents grammar rules, where the notation C -> (A, B) means that all occurrences of AB in that order get replaced by C?
identifier -> identifier-nondigit | (identifier,identifier-nondigit) | (identifier,digit)
identifier-nondigit -> nondigit | universal-character-name | other
digit -> 0 | 1 | 2 | ... | 9
non-digit -> _ | a | b | ... | z | A | ... | Z
I think I am confused because the documentation introduces 'preprocessing tokens' which I thought would be just labels of sequences of characters in the source produced without backtracking.
I.e. something like:
"15647  \n  \t abdsfg8rg \t" -> "DWLDLW"
// D .. digits, W ... whitespace, L ... letters
It seems like the lexer is doing the same thing as the parser (just building a tree). What is the reason for introducing the preprocessing tokens and tokens?
Does it mean that the processing should be done 'in two waves'?
I was expecting the lexer to just use some regular expressions and maybe a few rules. But it seems like the result of lexing is a sequence of trees that can have the roots keyword, identifier, constant, string-literal, punctuator.
Thank you for any clarifications.
2 Answers
I think I am confused because the documentation introduces 'preprocessing tokens' which I thought would be just labels of sequences of characters in the source produced without backtracking.
Preprocessing tokens are the input to the C preprocessor. In the process of translating C source code to an executable, the stream of preprocessing tokens and intervening whitespace is subject to manipulation by the preprocessor first, then the resulting stream of preprocessing tokens and whitespace is munged a bit further before being converted to (the Standard's word; perhaps "reinterpreted as" better conveys the idea) a stream of tokens. An overview of all this is presented in section 5.1.1.2 of the language standard.
The conversion from preprocessing tokens to tokens is a pretty straightforward mapping:
- identifier --> identifier or enumeration-constant (the choice is context-sensitive, but that can be worked around in practice by avoiding making the distinction until semantic analysis).
- pp-number --> integer-constant or floating-constant, as appropriate (two of the alternatives for constant)
- character-constant --> character-constant (one of the alternatives for constant)
- string-literal --> string-literal
- punctuator --> punctuator
- anything else remaining after deletion of preprocessing directives --> one or more single-character tokens
Note that header-name preprocessing tokens are a special case: there are ambiguities between each form of header-name and other possible tokenizations of preprocessing tokens. It is probably best to avoid analyzing anything as a header-name except in the context of an #include directive, and then you also don't need to worry about converting header-name preprocessing tokens to regular tokens because none of them will survive deletion of the preprocessing directives.
Additional details of the lexical analysis are presented in section 6.4 of the Standard and its subsections.
It seems like the lexer is doing the same thing as the parser (just building a tree).
I don't see how you draw that conclusion, but it is certainly true that the distinction between lexical analysis and parsing is artificial. It is not necessary to divide the language-analysis process that way, but it turns out often to be convenient, both for coding and for computation.
What is the reason for introducing the preprocessing tokens and tokens?
It is basically that standard C is really two languages in one: a preprocessing language and the C language itself. Early on, they were processed by altogether different programs, and preprocessing was optional. The preprocessor has a view of the units it operates with and upon that is not entirely consistent with the classifications of C grammar. Preprocessing-tokens are the units of the preprocessor's grammatic analysis and data, whereas tokens are the units of C's grammatic analysis.
Does it mean that the processing should be done 'in two waves'?
Logically, yes. In practice, I think most compilers integrate the two logical passes into a single physical pass through the source.
If you pay attention, you'll remark that the tokens are described with a regular grammar, this means that they could also be described with regular expressions. Why the editor of the standard preferred one formalism to the other is open to speculation, you could think that using only one formalism for both part was considered simpler.
The rules for white space and comments hint that the separation of concern between the parser and the lexer was present at the mind of the designer. You can't use the description as is in an lexer-less parser.
Note that the preprocessor is reason for the introduction of preprocessing-token. Things like header-name and pp-number have consequence on the behavior of the preprocessor. Note also that some tokens are recognized only in some contexts (notably <header> and "header" which is subtly different from "string").
Maya is a hardware enthusiast who tests and reviews smart home devices, smartphones, wearables, and audio gear. She focuses on practical consumer value and build quality.
