
Constructing a Confusion Matrix from Data Without Sklearn

I Am Trying to Construct a Confusion Matrix Without Using the Sklearn Library. I Am Having Trouble Correctly Forming the Confusion Matrix. Here's My Code: Def...
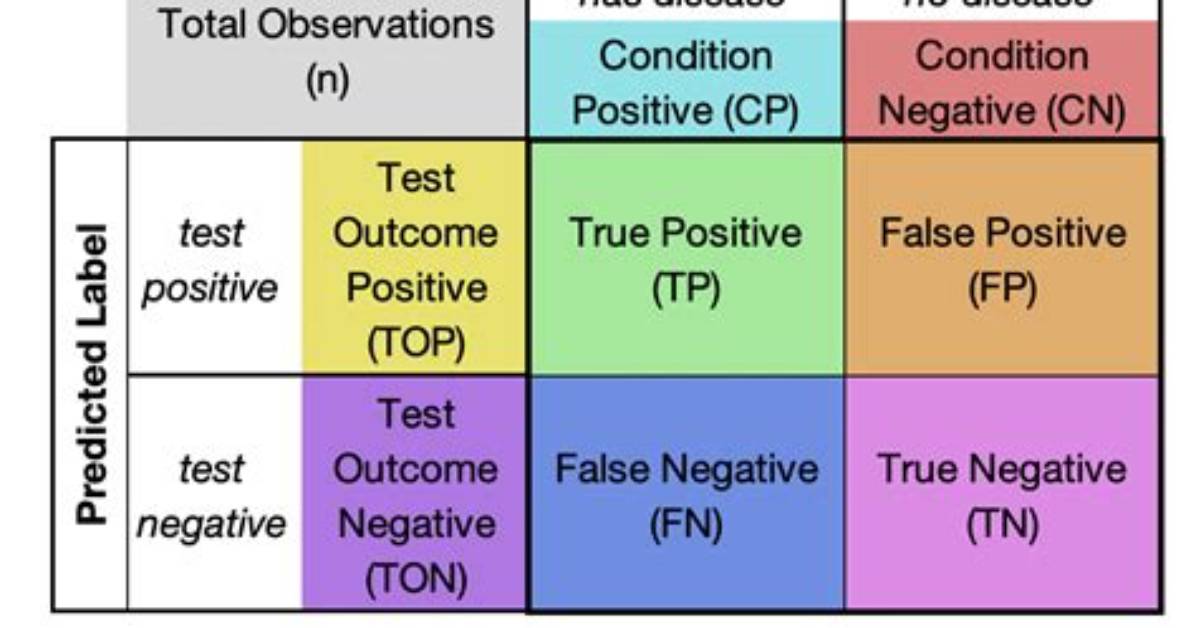
I am trying to construct a confusion matrix without using the sklearn library. I am having trouble correctly forming the confusion matrix. Here's my code:
def comp_confmat():
    currentDataClass = [1,3,3,2,5,5,3,2,1,4,3,2,1,1,2]
    predictedClass = [1,2,3,4,2,3,3,2,1,2,3,1,5,1,1]
    cm = []
    classes = int(max(currentDataClass) - min(currentDataClass)) + 1 #find number of classes

    for c1 in range(1,classes+1):#for every true class
        counts = []
        for c2 in range(1,classes+1):#for every predicted class
            count = 0
            for p in range(len(currentDataClass)):
                if currentDataClass[p] == predictedClass[p]:
                    count += 1
            counts.append(count)
        cm.append(counts)
    print(np.reshape(cm,(classes,classes)))
However this returns:
[[7 7 7 7 7]
[7 7 7 7 7]
[7 7 7 7 7]
[7 7 7 7 7]
[7 7 7 7 7]]
But I don't understand why each iteration results in 7 when I am reseting the count each time and it's looping through different values?
This is what I should be getting (using the sklearn's confusion_matrix function):
[[3 0 0 0 1]
[2 1 0 1 0]
[0 1 3 0 0]
[0 1 0 0 0]
[0 1 1 0 0]]
3 Answers
You can derive the confusion matrix by counting the number of instances in each combination of actual and predicted classes as follows:
import numpy as np

def comp_confmat(actual, predicted):

    # extract the different classes
    classes = np.unique(actual)

    # initialize the confusion matrix
    confmat = np.zeros((len(classes), len(classes)))

    # loop across the different combinations of actual / predicted classes
    for i in range(len(classes)):
        for j in range(len(classes)):

           # count the number of instances in each combination of actual / predicted classes
           confmat[i, j] = np.sum((actual == classes[i]) & (predicted == classes[j]))

    return confmat

# sample data
actual = [1, 3, 3, 2, 5, 5, 3, 2, 1, 4, 3, 2, 1, 1, 2]
predicted = [1, 2, 3, 4, 2, 3, 3, 2, 1, 2, 3, 1, 5, 1, 1]

# confusion matrix
print(comp_confmat(actual, predicted))
# [[3. 0. 0. 0. 1.]
#  [2. 1. 0. 1. 0.]
#  [0. 1. 3. 0. 0.]
#  [0. 1. 0. 0. 0.]
#  [0. 1. 1. 0. 0.]]
In your innermost loop, there should be a case distinction: Currently this loop counts agreement, but you only want that if actually c1 == c2.
Here's another way, using nested list comprehensions:
currentDataClass = [1,3,3,2,5,5,3,2,1,4,3,2,1,1,2]
predictedClass = [1,2,3,4,2,3,3,2,1,2,3,1,5,1,1]

classes = int(max(currentDataClass) - min(currentDataClass)) + 1 #find number of classes

counts = [[sum([(currentDataClass[i] == true_class) and (predictedClass[i] == pred_class)
                for i in range(len(currentDataClass))])
           for pred_class in range(1, classes + 1)]
           for true_class in range(1, classes + 1)]
counts
[[3, 0, 0, 0, 1],
 [2, 1, 0, 1, 0],
 [0, 1, 3, 0, 0],
 [0, 1, 0, 0, 0],
 [0, 1, 1, 0, 0]]
Here is my solution using numpy and pandas:
import numpy as np
import pandas as pd

true_classes = [1, 3, 3, 2, 5, 5, 3, 2, 1, 4, 3, 2, 1, 1, 2]
predicted_classes = [1, 2, 3, 4, 2, 3, 3, 2, 1, 2, 3, 1, 5, 1, 1]

classes = set(true_classes)
number_of_classes = len(classes)

conf_matrix = pd.DataFrame(
    np.zeros((number_of_classes, number_of_classes),dtype=int),
    index=classes,
    columns=classes)

for true_label, prediction in zip(true_classes ,predicted_classes):
    # Each pair of (true_label, prediction) is a position in the confusion matrix (row, column)
    # Basically here we are counting how many times we have each pair.
    # The counting will be placed at the matrix index (true_label/row, prediction/column)

    conf_matrix.loc[true_label, prediction] += 1

print(conf_matrix.values)
[[3 0 0 0 1]
 [2 1 0 1 0]
 [0 1 3 0 0]
 [0 1 0 0 0]
 [0 1 1 0 0]]
Sarah Jenkins is a veteran tech journalist with over 12 years of experience covering artificial intelligence, mobile innovations, and digital ethics. Her insights have appeared in leading technology publications worldwide.
