
Convert Select Columns in Pandas Dataframe to Numpy Array

I Would Like to Convert Everything but the First Column of a Pandas Dataframe into a Numpy Array. for Some Reason Using the Columns= Parameter of Dataframe...
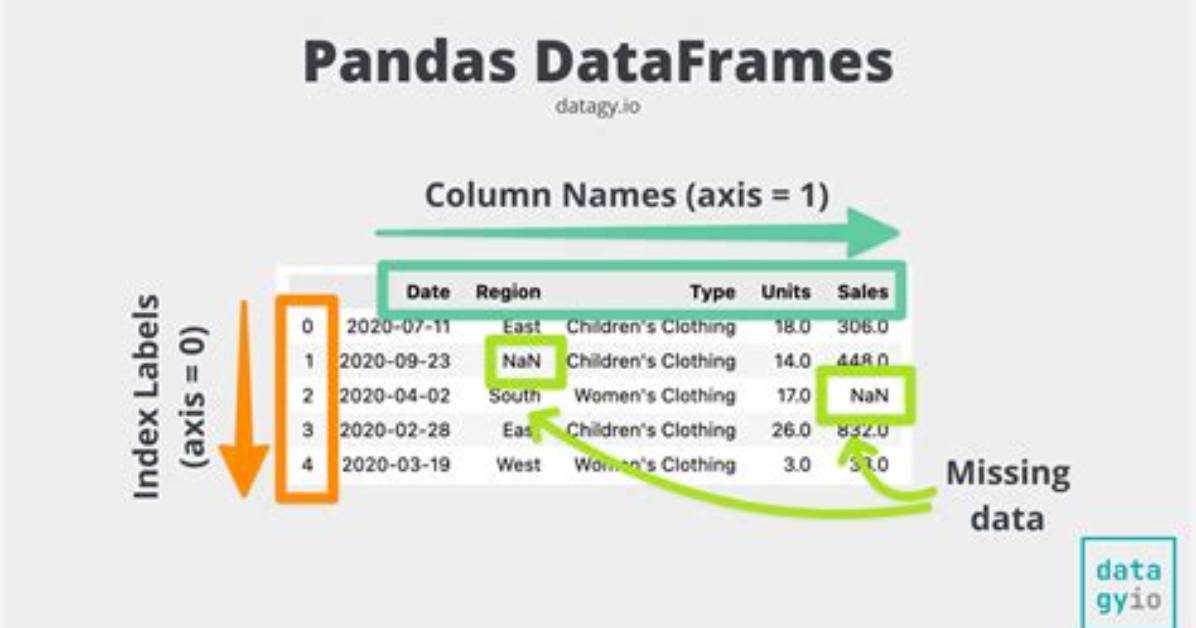
I would like to convert everything but the first column of a pandas dataframe into a numpy array. For some reason using the columns= parameter of DataFrame.to_matrix() is not working.
df:
  viz  a1_count  a1_mean     a1_std
0   n         3        2   0.816497
1   n         0      NaN        NaN
2   n         2       51  50.000000
I tried X=df.as_matrix(columns=[df[1:]]) but this yields an array of all NaNs
7 Answers
the easy way is the "values" property df.iloc[:,1:].values
a=df.iloc[:,1:]
b=df.iloc[:,1:].values

print(type(df))
print(type(a))
print(type(b))
so, you can get type
<class 'pandas.core.frame.DataFrame'>
<class 'pandas.core.frame.DataFrame'>
<class 'numpy.ndarray'>
Please use the Pandas to_numpy() method. Below is an example--
>>> import pandas as pd
>>> df = pd.DataFrame({"A":[1, 2], "B":[3, 4], "C":[5, 6]})
>>> df
    A  B  C
 0  1  3  5
 1  2  4  6
>>> s_array = df[["A", "B", "C"]].to_numpy()
>>> s_array

array([[1, 3, 5],
   [2, 4, 6]])

>>> t_array = df[["B", "C"]].to_numpy()
>>> print (t_array)

[[3 5]
 [4 6]]
Hope this helps. You can select any number of columns using
columns = ['col1', 'col2', 'col3']
df1 = df[columns]
Then apply to_numpy() method.
The columns parameter accepts a collection of column names. You're passing a list containing a dataframe with two rows:
>>> [df[1:]]
[  viz  a1_count  a1_mean  a1_std
1   n         0      NaN     NaN
2   n         2       51      50]
>>> df.as_matrix(columns=[df[1:]])
array([[ nan,  nan],
       [ nan,  nan],
       [ nan,  nan]])
Instead, pass the column names you want:
>>> df.columns[1:]
Index(['a1_count', 'a1_mean', 'a1_std'], dtype='object')
>>> df.as_matrix(columns=df.columns[1:])
array([[  3.      ,   2.      ,   0.816497],
       [  0.      ,        nan,        nan],
       [  2.      ,  51.      ,  50.      ]])
Hope this easy one liner helps:
cols_as_np = df[df.columns[1:]].to_numpy()
Instead of .as_matrix(), use .values, because the first one was deprecated. Here is the contribution:
The fastest and easiest way is to use .as_matrix(). One short line:
df.iloc[:,[1,2,3]].as_matrix()
Gives:
array([[3, 2, 0.816497],
   [0, 'NaN', 'NaN'],
   [2, 51, 50.0]], dtype=object)
By using indices of the columns, you can use this code for any dataframe with different column names.
Here are the steps for your example:
import pandas as pd
columns = ['viz', 'a1_count', 'a1_mean', 'a1_std']
index = [0,1,2]
vals = {'viz': ['n','n','n'], 'a1_count': [3,0,2], 'a1_mean': [2,'NaN', 51], 'a1_std': [0.816497, 'NaN', 50.000000]}
df = pd.DataFrame(vals, columns=columns, index=index)
Gives:
   viz  a1_count a1_mean    a1_std
0   n         3       2  0.816497
1   n         0     NaN       NaN
2   n         2      51        50
Then:
x1 = df.iloc[:,[1,2,3]].as_matrix()
Gives:
array([[3, 2, 0.816497],
   [0, 'NaN', 'NaN'],
   [2, 51, 50.0]], dtype=object)
Where x1 is numpy.ndarray.
James Sterling reports on renewable energy developments, climate policy, ecological conservation, and green tech innovations around the globe.
