
Create Nice Column Output in Python

I Am Trying to Create a Nice Column List in Python for Use with Commandline Admin Tools Which I Create. Basicly, I Want a List Like: [['A', 'B', 'C']...
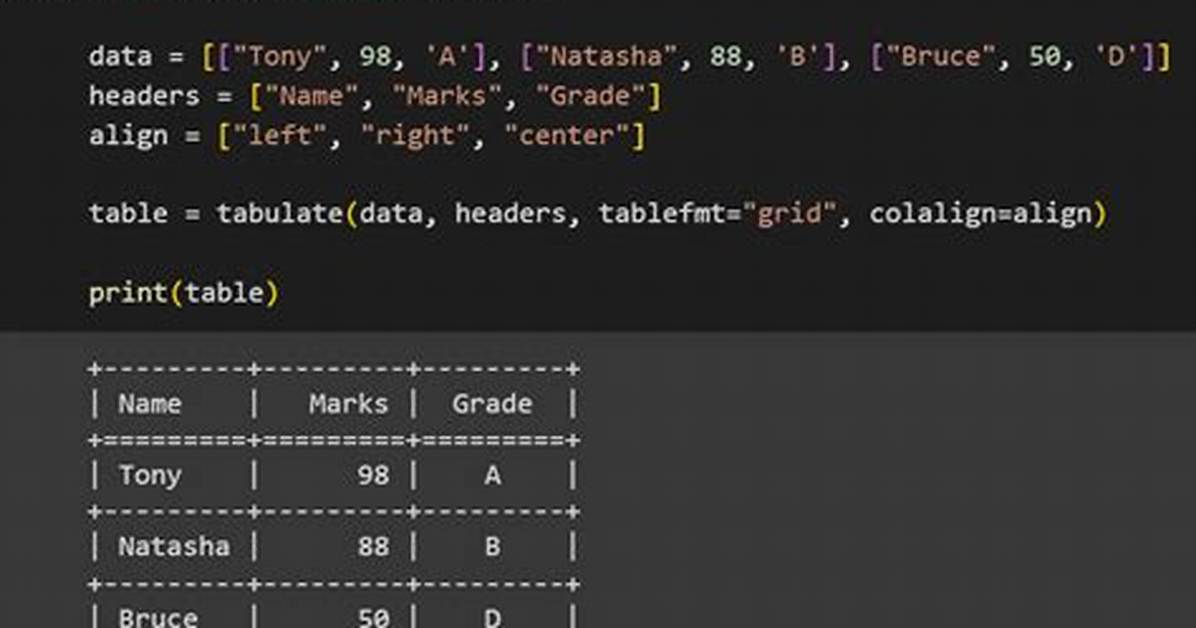
I am trying to create a nice column list in python for use with commandline admin tools which I create.
Basicly, I want a list like:
[['a', 'b', 'c'], ['aaaaaaaaaa', 'b', 'c'], ['a', 'bbbbbbbbbb', 'c']]
To turn into:
a            b            c
aaaaaaaaaa   b            c
a            bbbbbbbbbb   c
Using plain tabs wont do the trick here because I don't know the longest data in each row.
This is the same behavior as 'column -t' in Linux..
$ echo -e "a b c\naaaaaaaaaa b c\na bbbbbbbbbb c"
a b c
aaaaaaaaaa b c
a bbbbbbbbbb c

$ echo -e "a b c\naaaaaaaaaa b c\na bbbbbbbbbb c" | column -t
a           b           c
aaaaaaaaaa  b           c
a           bbbbbbbbbb  c
I have looked around for various python libraries to do this but can't find anything useful.
22 Answers
Since Python 2.6+, you can use a format string in the following way to set the columns to a minimum of 20 characters and align text to right.
table_data = [
    ['a', 'b', 'c'],
    ['aaaaaaaaaa', 'b', 'c'],
    ['a', 'bbbbbbbbbb', 'c']
]
for row in table_data:
    print("{: >20} {: >20} {: >20}".format(*row))
Output:
               a                    b                    c
      aaaaaaaaaa                    b                    c
               a           bbbbbbbbbb                    c
data = [['a', 'b', 'c'], ['aaaaaaaaaa', 'b', 'c'], ['a', 'bbbbbbbbbb', 'c']]

col_width = max(len(word) for row in data for word in row) + 2  # padding
for row in data:
    print "".join(word.ljust(col_width) for word in row)

a            b            c
aaaaaaaaaa   b            c
a            bbbbbbbbbb   c
What this does is calculate the longest data entry to determine the column width, then use .ljust() to add the necessary padding when printing out each column.
I came here with the same requirements but @lvc and @Preet's answers seems more inline with what column -t produces in that columns have different widths:
>>> rows =  [   ['a',           'b',            'c',    'd']
...         ,   ['aaaaaaaaaa',  'b',            'c',    'd']
...         ,   ['a',           'bbbbbbbbbb',   'c',    'd']
...         ]
...
>>> widths = [max(map(len, col)) for col in zip(*rows)]
>>> for row in rows:
...     print "  ".join((val.ljust(width) for val, width in zip(row, widths)))
...
a           b           c  d
aaaaaaaaaa  b           c  d
a           bbbbbbbbbb  c  d
This is a little late to the party, and a shameless plug for a package I wrote, but you can also check out the Columnar package.
It takes a list of lists of input and a list of headers and outputs a table-formatted string. This snippet creates a docker-esque table:
from columnar import columnar

headers = ['name', 'id', 'host', 'notes']

data = [
    ['busybox', 'c3c37d5d-38d2-409f-8d02-600fd9d51239', 'linuxnode-1-292735', 'Test server.'],
    ['alpine-python', '6bb77855-0fda-45a9-b553-e19e1a795f1e', 'linuxnode-2-249253', 'The one that runs python.'],
    ['redis', 'afb648ba-ac97-4fb2-8953-9a5b5f39663e', 'linuxnode-3-3416918', 'For queues and stuff.'],
    ['app-server', 'b866cd0f-bf80-40c7-84e3-c40891ec68f9', 'linuxnode-4-295918', 'A popular destination.'],
    ['nginx', '76fea0f0-aa53-4911-b7e4-fae28c2e469b', 'linuxnode-5-292735', 'Traffic Cop'],
]

table = columnar(data, headers, no_borders=True)
print(table)
Or you can get a little fancier with colors and borders.
To read more about the column-sizing algorithm and see the rest of the API you can check out the link above or see the Columnar GitHub Repo
You have to do this with 2 passes:
- get the maximum width of each column.
- formatting the columns using our knowledge of max width from the first pass using
str.ljust()andstr.rjust()
Wow, only 17 answers. The zen of python says "There should be one-- and preferably only one --obvious way to do it."
So here is an 18th way to do it: The tabulate package supports a bunch of data types that it can display as tables, here is a simple example adapted from their docs:
from tabulate import tabulate

table = [["Sun",696000,1989100000],
         ["Earth",6371,5973.6],
         ["Moon",1737,73.5],
         ["Mars",3390,641.85]]

print(tabulate(table, headers=["Planet","R (km)", "mass (x 10^29 kg)"]))
which outputs
Planet      R (km)    mass (x 10^29 kg)
--------  --------  -------------------
Sun         696000           1.9891e+09
Earth         6371        5973.6
Moon          1737          73.5
Mars          3390         641.85
Transposing the columns like that is a job for zip:
>>> a = [['a', 'b', 'c'], ['aaaaaaaaaa', 'b', 'c'], ['a', 'bbbbbbbbbb', 'c']]
>>> list(zip(*a))
[('a', 'aaaaaaaaaa', 'a'), ('b', 'b', 'bbbbbbbbbb'), ('c', 'c', 'c')]
To find the required length of each column, you can use max:
>>> trans_a = zip(*a)
>>> [max(len(c) for c in b) for b in trans_a]
[10, 10, 1]
Which you can use, with suitable padding, to construct strings to pass to print:
>>> col_lenghts = [max(len(c) for c in b) for b in trans_a]
>>> padding = ' ' # You might want more
>>> padding.join(s.ljust(l) for s,l in zip(a[0], col_lenghts))
'a          b          c'
To get fancier tables like
---------------------------------------------------
| First Name | Last Name        | Age | Position  |
---------------------------------------------------
| John       | Smith            | 24  | Software  |
|            |                  |     | Engineer  |
---------------------------------------------------
| Mary       | Brohowski        | 23  | Sales     |
|            |                  |     | Manager   |
---------------------------------------------------
| Aristidis  | Papageorgopoulos | 28  | Senior    |
|            |                  |     | Reseacher |
---------------------------------------------------
you can use this Python recipe:
'''
From
PSF License
'''
import cStringIO,operator

def indent(rows, hasHeader=False, headerChar='-', delim=' | ', justify='left',
           separateRows=False, prefix='', postfix='', wrapfunc=lambda x:x):
    """Indents a table by column.
       - rows: A sequence of sequences of items, one sequence per row.
       - hasHeader: True if the first row consists of the columns' names.
       - headerChar: Character to be used for the row separator line
         (if hasHeader==True or separateRows==True).
       - delim: The column delimiter.
       - justify: Determines how are data justified in their column.
         Valid values are 'left','right' and 'center'.
       - separateRows: True if rows are to be separated by a line
         of 'headerChar's.
       - prefix: A string prepended to each printed row.
       - postfix: A string appended to each printed row.
       - wrapfunc: A function f(text) for wrapping text; each element in
         the table is first wrapped by this function."""
    # closure for breaking logical rows to physical, using wrapfunc
    def rowWrapper(row):
        newRows = [wrapfunc(item).split('\n') for item in row]
        return [[substr or '' for substr in item] for item in map(None,*newRows)]
    # break each logical row into one or more physical ones
    logicalRows = [rowWrapper(row) for row in rows]
    # columns of physical rows
    columns = map(None,*reduce(operator.add,logicalRows))
    # get the maximum of each column by the string length of its items
    maxWidths = [max([len(str(item)) for item in column]) for column in columns]
    rowSeparator = headerChar * (len(prefix) + len(postfix) + sum(maxWidths) + \
                                 len(delim)*(len(maxWidths)-1))
    # select the appropriate justify method
    justify = {'center':str.center, 'right':str.rjust, 'left':str.ljust}[justify.lower()]
    output=cStringIO.StringIO()
    if separateRows: print >> output, rowSeparator
    for physicalRows in logicalRows:
        for row in physicalRows:
            print >> output, \
                prefix \
                + delim.join([justify(str(item),width) for (item,width) in zip(row,maxWidths)]) \
                + postfix
        if separateRows or hasHeader: print >> output, rowSeparator; hasHeader=False
    return output.getvalue()

# written by Mike Brown
#
def wrap_onspace(text, width):
    """
    A word-wrap function that preserves existing line breaks
    and most spaces in the text. Expects that existing line
    breaks are posix newlines (\n).
    """
    return reduce(lambda line, word, width=width: '%s%s%s' %
                  (line,
                   ' \n'[(len(line[line.rfind('\n')+1:])
                         + len(word.split('\n',1)[0]
                              ) >= width)],
                   word),
                  text.split(' ')
                 )

import re
def wrap_onspace_strict(text, width):
    """Similar to wrap_onspace, but enforces the width constraint:
       words longer than width are split."""
    wordRegex = re.compile(r'\S{'+str(width)+r',}')
    return wrap_onspace(wordRegex.sub(lambda m: wrap_always(m.group(),width),text),width)

import math
def wrap_always(text, width):
    """A simple word-wrap function that wraps text on exactly width characters.
       It doesn't split the text in words."""
    return '\n'.join([ text[width*i:width*(i+1)] \
                       for i in xrange(int(math.ceil(1.*len(text)/width))) ])

if __name__ == '__main__':
    labels = ('First Name', 'Last Name', 'Age', 'Position')
    data = \
    '''John,Smith,24,Software Engineer
       Mary,Brohowski,23,Sales Manager
       Aristidis,Papageorgopoulos,28,Senior Reseacher'''
    rows = [row.strip().split(',')  for row in data.splitlines()]

    print 'Without wrapping function\n'
    print indent([labels]+rows, hasHeader=True)
    # test indent with different wrapping functions
    width = 10
    for wrapper in (wrap_always,wrap_onspace,wrap_onspace_strict):
        print 'Wrapping function: %s(x,width=%d)\n' % (wrapper.__name__,width)
        print indent([labels]+rows, hasHeader=True, separateRows=True,
                     prefix='| ', postfix=' |',
                     wrapfunc=lambda x: wrapper(x,width))

    # output:
    #
    #Without wrapping function
    #
    #First Name | Last Name        | Age | Position
    #-------------------------------------------------------
    #John       | Smith            | 24  | Software Engineer
    #Mary       | Brohowski        | 23  | Sales Manager
    #Aristidis  | Papageorgopoulos | 28  | Senior Reseacher
    #
    #Wrapping function: wrap_always(x,width=10)
    #
    #----------------------------------------------
    #| First Name | Last Name  | Age | Position   |
    #----------------------------------------------
    #| John       | Smith      | 24  | Software E |
    #|            |            |     | ngineer    |
    #----------------------------------------------
    #| Mary       | Brohowski  | 23  | Sales Mana |
    #|            |            |     | ger        |
    #----------------------------------------------
    #| Aristidis  | Papageorgo | 28  | Senior Res |
    #|            | poulos     |     | eacher     |
    #----------------------------------------------
    #
    #Wrapping function: wrap_onspace(x,width=10)
    #
    #---------------------------------------------------
    #| First Name | Last Name        | Age | Position  |
    #---------------------------------------------------
    #| John       | Smith            | 24  | Software  |
    #|            |                  |     | Engineer  |
    #---------------------------------------------------
    #| Mary       | Brohowski        | 23  | Sales     |
    #|            |                  |     | Manager   |
    #---------------------------------------------------
    #| Aristidis  | Papageorgopoulos | 28  | Senior    |
    #|            |                  |     | Reseacher |
    #---------------------------------------------------
    #
    #Wrapping function: wrap_onspace_strict(x,width=10)
    #
    #---------------------------------------------
    #| First Name | Last Name  | Age | Position  |
    #---------------------------------------------
    #| John       | Smith      | 24  | Software  |
    #|            |            |     | Engineer  |
    #---------------------------------------------
    #| Mary       | Brohowski  | 23  | Sales     |
    #|            |            |     | Manager   |
    #---------------------------------------------
    #| Aristidis  | Papageorgo | 28  | Senior    |
    #|            | poulos     |     | Reseacher |
    #---------------------------------------------
The Python recipe page contains a few improvements on it.
pandas based solution with creating dataframe:
import pandas as pd
l = [['a', 'b', 'c'], ['aaaaaaaaaa', 'b', 'c'], ['a', 'bbbbbbbbbb', 'c']]
df = pd.DataFrame(l)

print(df)
            0           1  2
0           a           b  c
1  aaaaaaaaaa           b  c
2           a  bbbbbbbbbb  c
To remove index and header values to create output what you want you could use to_string method:
result = df.to_string(index=False, header=False)

print(result)
          a           b  c
 aaaaaaaaaa           b  c
          a  bbbbbbbbbb  c
Scolp is a new library that lets you pretty print streaming columnar data easily while auto-adjusting column width.
(Disclaimer: I am the author)
Must Read
For lazy people
that are using Python 3.* and Pandas/Geopandas; universal simple in-class approach (for 'normal' script just remove self):
Function colorize:
    def colorize(self,s,color):
        s = color+str(s)+"\033[0m"
        return s
Header:
print('{0:<23} {1:>24} {2:>26} {3:>26} {4:>11} {5:>11}'.format('Road name','Classification','Function','Form of road','Length','Distance') )
and then data from Pandas/Geopandas dataframe:
            for index, row in clipped.iterrows():
                rdName      = self.colorize(row['name1'],"\033[32m")
                rdClass     = self.colorize(row['roadClassification'],"\033[93m")
                rdFunction  = self.colorize(row['roadFunction'],"\033[33m")
                rdForm      = self.colorize(row['formOfWay'],"\033[94m")
                rdLength    = self.colorize(row['length'],"\033[97m")
                rdDistance  = self.colorize(row['distance'],"\033[96m")
                print('{0:<30} {1:>35} {2:>35} {3:>35} {4:>20} {5:>20}'.format(rdName,rdClass,rdFunction,rdForm,rdLength,rdDistance) )
Meaning of {0:<30} {1:>35} {2:>35} {3:>35} {4:>20} {5:>20}:
0, 1, 2, 3, 4, 5 -> columns, there are 6 in total in this case
30, 35, 20 -> width of column (note that you'll have to add length of \033[96m - this for Python is a string as well), just experiment :)
>, < -> justify: right, left (there is = for filling with zeros as well)
If you want to distinct e.g. max value, you'll have to switch to special Pandas style function, but suppose that's far enough to present data on terminal window.
Marcus Vance is a cybersecurity auditor and technology writer dedicated to educating the public about online safety, data privacy regulations, enterprise security, and emerging cyber threats.
