
Difference Between Dataframe, Dataset, and Rdd in Spark

I'm Just Wondering What Is the Difference Between an Rdd and Dataframe (Spark 2.0.0 Dataframe Is a Mere Type Alias for Dataset[Row]) in Apache Spark? Can You...
I'm just wondering what is the difference between an RDD and DataFrame (Spark 2.0.0 DataFrame is a mere type alias for Dataset[Row]) in Apache Spark?
Can you convert one to the other?
14 Answers
A DataFrame is defined well with a google search for "DataFrame definition":
A data frame is a table, or two-dimensional array-like structure, in which each column contains measurements on one variable, and each row contains one case.
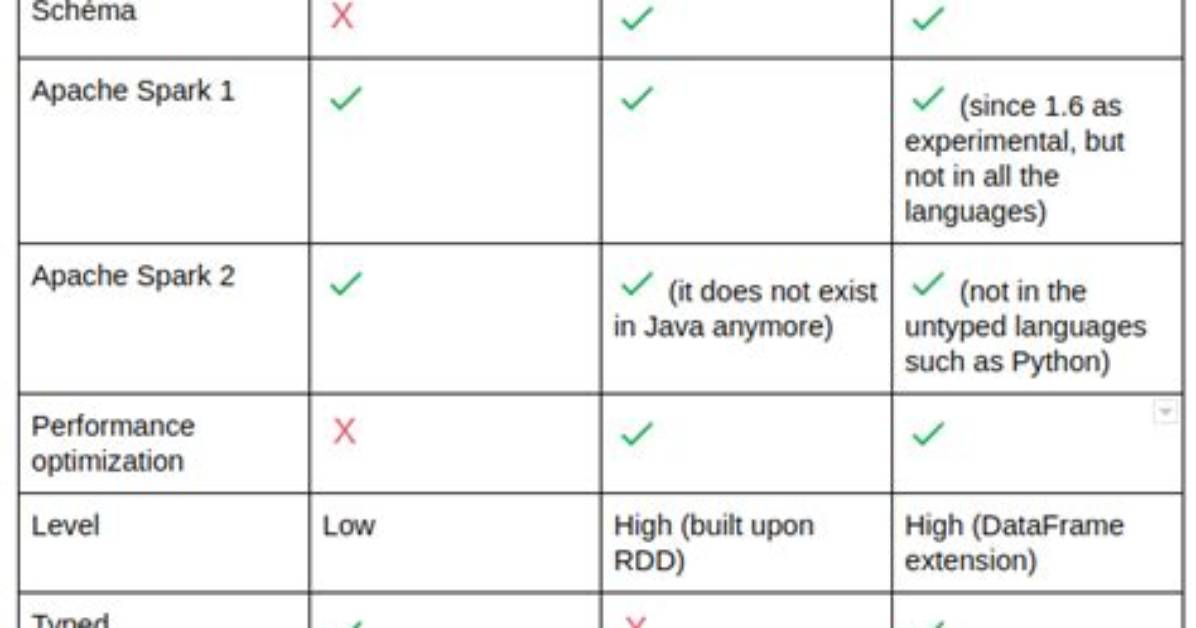
So, a DataFrame has additional metadata due to its tabular format, which allows Spark to run certain optimizations on the finalized query.
An RDD, on the other hand, is merely a Resilient Distributed Dataset that is more of a blackbox of data that cannot be optimized as the operations that can be performed against it, are not as constrained.
However, you can go from a DataFrame to an RDD via its rdd method, and you can go from an RDD to a DataFrame (if the RDD is in a tabular format) via the toDF method
In general it is recommended to use a DataFrame where possible due to the built in query optimization.
First thing is
DataFramewas evolved fromSchemaRDD.
Yes.. conversion between Dataframe and RDD is absolutely possible.
Below are some sample code snippets.
df.rddisRDD[Row]
Below are some of options to create dataframe.
1)
yourrddOffrow.toDFconverts toDataFrame.2) Using
createDataFrameof sql contextval df = spark.createDataFrame(rddOfRow, schema)
where schema can be from some of below options as described by nice SO post..
From scala case class and scala reflection apiimport org.apache.spark.sql.catalyst.ScalaReflection val schema = ScalaReflection.schemaFor[YourScalacaseClass].dataType.asInstanceOf[StructType]OR using
Encodersimport org.apache.spark.sql.Encoders val mySchema = Encoders.product[MyCaseClass].schemaas described by Schema can also be created using
StructTypeandStructFieldval schema = new StructType() .add(StructField("id", StringType, true)) .add(StructField("col1", DoubleType, true)) .add(StructField("col2", DoubleType, true)) etc...
In fact there Are Now 3 Apache Spark APIs..
-
Must Read
RDDAPI :
The
RDD(Resilient Distributed Dataset) API has been in Spark since the 1.0 release.The
RDDAPI provides many transformation methods, such asmap(),filter(), andreduce() for performing computations on the data. Each of these methods results in a newRDDrepresenting the transformed data. However, these methods are just defining the operations to be performed and the transformations are not performed until an action method is called. Examples of action methods arecollect() andsaveAsObjectFile().
RDD Example:
rdd.filter(_.age > 21) // transformation
   .map(_.last)// transformation
.saveAsObjectFile("under21.bin") // action
Example: Filter by attribute with RDD
rdd.filter(_.age > 21)
Sarah Jenkins is a veteran tech journalist with over 12 years of experience covering artificial intelligence, mobile innovations, and digital ethics. Her insights have appeared in leading technology publications worldwide.
