
Does Spark Run Hadoop

Spark Is a Fast and General Processing Engine Compatible with Hadoop Data. It Can Run in Hadoop Clusters Through Yarn or Spark’s Standalone Mode, and It Can...
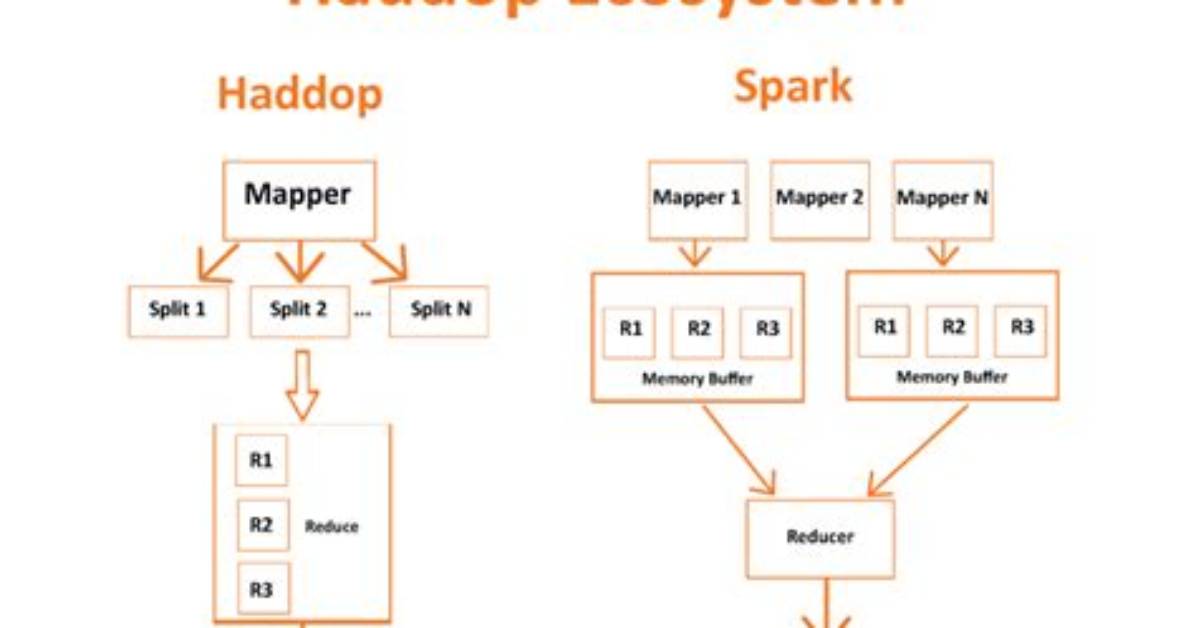
Spark is a fast and general processing engine compatible with Hadoop data. It can run in Hadoop clusters through YARN or Spark’s standalone mode, and it can process data in HDFS, HBase, Cassandra, Hive, and any Hadoop InputFormat.
Is Hadoop mandatory for Spark?
Yes, Apache Spark can run without Hadoop, standalone, or in the cloud. Spark doesn’t need a Hadoop cluster to work. Spark can read and then process data from other file systems as well.
How Spark Works on Hadoop?
Apache Mesos: Spark runs on top of Mesos, a cluster manager system which provides efficient resource isolation across distributed applications, including MPI and Hadoop. Mesos enables fine grained sharing which allows a Spark job to dynamically take advantage of the idle resources in the cluster during its execution.
Alexander Ross has covered the video game industry for a decade, writing deep dives on game design, esports tournaments, VR developments, and gaming culture.
