
Error While Running Spark Job Because of the Native Files Missing

I Was Getting This Error Java. Lang. Runtimeexception: Native Snappy Library Not Available: This Version of Libhadoop Was Built Without Snappy Support. While...
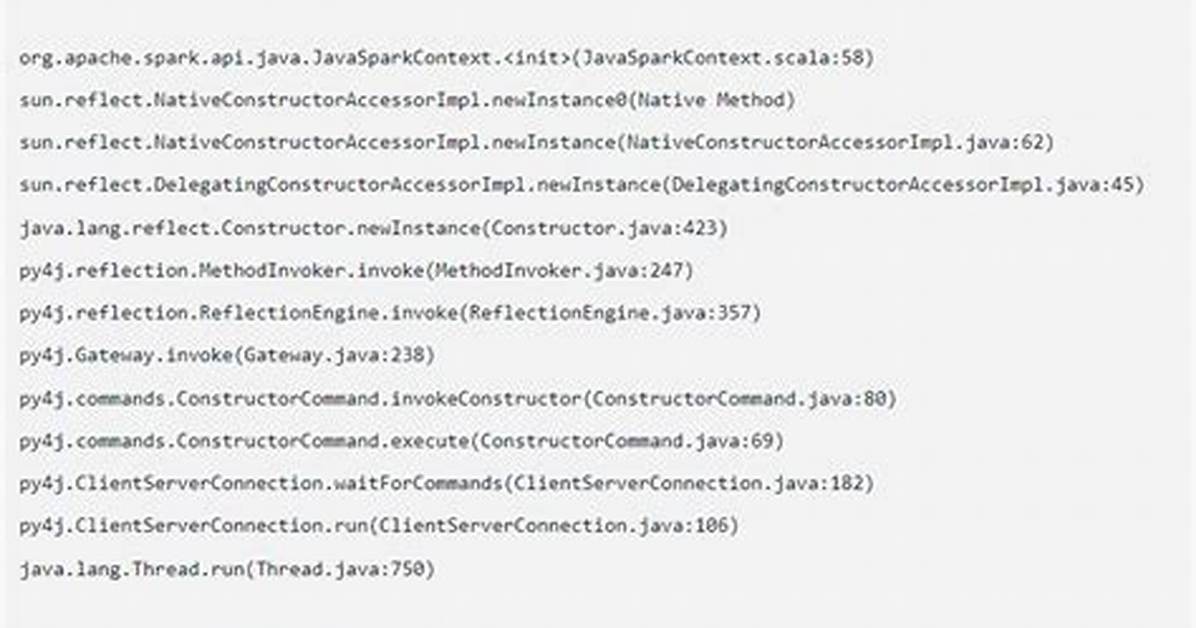
I was getting this error java.lang.RuntimeException: native snappy library not available: this version of libhadoop was built without snappy support. while running a spark submit job.
What I did was copied libhadoop.so and libsnappy.so inside java/java-1.8.0-openjdk-1.8.0.212.b04-0.e11_10.x86_64/jre/lib/amd64/ Then the process has been running without any issues. Found solution here .
Before I copying I was adding --driver-library-path /usr/hdp/current/hadoop-client/lib/native/
as part of the submit job but that didnt work, I also tried adding it to HADOOP_OPTS, all in vain.
Can someone explain how copying it to java amd64 folder made things work?
1 Answer
The executors are what need the native libraries, not the Spark driver, which would explain why --driver-library-path wouldn't work.
It's unclear how/where you set HADOOP_OPTS, but it's probably a similar issue.
Your solution works because you now have made every Java process have access to those files, not only the Hadoop/Spark processes.
Chloe Bennett explores the intersection of pop culture, streaming entertainment, digital trends, and contemporary lifestyle. Her weekly commentary reaches thousands of culture enthusiasts.
