
Gunicorn Worker Timeout Error

I Have Setup Gunicorn with 3 Workers 30 Worker Connections and Using Eventlet Worker Class. It Is Setup Behind Nginx. After Every Few Requests, I See This in...
I have setup gunicorn with 3 workers 30 worker connections and using eventlet worker class. It is setup behind Nginx. After every few requests, I see this in the logs.
[ERROR] gunicorn.error: WORKER TIMEOUT (pid:23475)
None
[INFO] gunicorn.error: Booting worker with pid: 23514
Why is this happening? How can I figure out whats going wrong?
thanks
16 Answers
We had the same problem using Django+nginx+gunicorn. From Gunicorn documentation we have configured the graceful-timeout that made almost no difference.
After some testings, we found the solution, the parameter to configure is: timeout (And not graceful timeout). It works like a clock..
So, Do:
1) open the gunicorn configuration file
2) set the TIMEOUT to what ever you need - the value is in seconds
NUM_WORKERS=3
TIMEOUT=120

exec gunicorn ${DJANGO_WSGI_MODULE}:application \
--name $NAME \
--workers $NUM_WORKERS \
--timeout $TIMEOUT \
--log-level=debug \
--bind=127.0.0.1:9000 \
--pid=$PIDFILE
On Google Cloud
Just add --timeout 90 to entrypoint in app.yaml
entrypoint: gunicorn -b :$PORT main:app --timeout 90
Run Gunicorn with --log-level debug.
It should give you an app stack trace.
Is this endpoint taking too many time?
Maybe you are using flask without asynchronous support, so every request will block the call. To create async support without make difficult, add the gevent worker.
With gevent, a new call will spawn a new thread, and you app will be able to receive more requests
pip install gevent
gunicon .... --worker-class gevent
The Microsoft Azure official documentation for running Flask Apps on Azure App Services (Linux App) states the use of timeout as 600
gunicorn --bind=0.0.0.0 --timeout 600 application:app
Could it be this?
Other possibilities could be your response is taking too long or is stuck waiting.
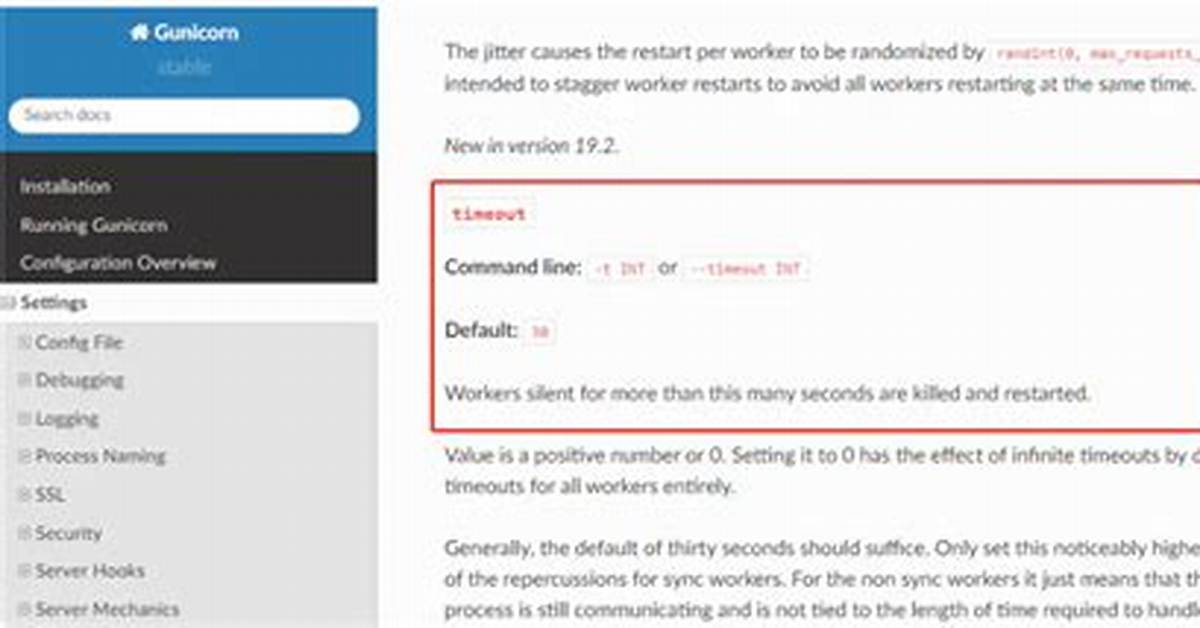
WORKER TIMEOUT means your application cannot response to the request in a defined amount of time. You can set this using gunicorn timeout settings. Some application need more time to response than another.
Another thing that may affect this is choosing the worker type
The default synchronous workers assume that your application is resource-bound in terms of CPU and network bandwidth. Generally this means that your application shouldn’t do anything that takes an undefined amount of time. An example of something that takes an undefined amount of time is a request to the internet. At some point the external network will fail in such a way that clients will pile up on your servers. So, in this sense, any web application which makes outgoing requests to APIs will benefit from an asynchronous worker.
When I got the same problem as yours (I was trying to deploy my application using Docker Swarm), I've tried to increase the timeout and using another type of worker class. But all failed.
And then I suddenly realised I was limitting my resource too low for the service inside my compose file. This is the thing slowed down the application in my case
deploy:
  replicas: 5
  resources:
    limits:
      cpus: "0.1"
      memory: 50M
  restart_policy:
    condition: on-failure
So I suggest you to check what thing slowing down your application in the first place
I've got the same problem in Docker.
In Docker I keep trained LightGBM model + Flask serving requests. As HTTP server I used gunicorn 19.9.0. When I run my code locally on my Mac laptop everything worked just perfect, but when I ran the app in Docker my POST JSON requests were freezing for some time, then gunicorn worker had been failing with [CRITICAL] WORKER TIMEOUT exception.
I tried tons of different approaches, but the only one solved my issue was adding worker_class=gthread.
Here is my complete config:
import multiprocessing

workers = multiprocessing.cpu_count() * 2 + 1
accesslog = "-" # STDOUT
access_log_format = '%(h)s %(l)s %(u)s %(t)s "%(r)s" %(s)s %(b)s "%(q)s" "%(D)s"'
bind = "0.0.0.0:5000"
keepalive = 120
timeout = 120
worker_class = "gthread"
threads = 3
This worked for me:
gunicorn app:app -b :8080 --timeout 120 --workers=3 --threads=3 --worker-connections=1000
If you have eventlet add:
--worker-class=eventlet
If you have gevent add:
--worker-class=gevent
I had very similar problem, I also tried using "runserver" to see if I could find anything but all I had was a message Killed
So I thought it could be resource problem, and I went ahead to give more RAM to the instance, and it worked.
You need to used an other worker type class an async one like gevent or tornado see this for more explanation : First explantion :
You may also want to install Eventlet or Gevent if you expect that your application code may need to pause for extended periods of time during request processing
Second one :
The default synchronous workers assume that your application is resource bound in terms of CPU and network bandwidth. Generally this means that your application shouldn’t do anything that takes an undefined amount of time. For instance, a request to the internet meets this criteria. At some point the external network will fail in such a way that clients will pile up on your servers.
If you are using GCP then you have to set workers per instance type.
Link to GCP best practices
timeout is a key parameter to this problem.
however it's not suit for me.
i found there is not gunicorn timeout error when i set workers=1.
when i look though my code, i found some socket connect (socket.send & socket.recv) in server init.
socket.recv will block my code and that's why it always timeout when workers>1
hope to give some ideas to the people who have some problem with me
For me, the solution was to add --timeout 90 to my entrypoint, but it wasn't working because I had TWO entrypoints defined, one in app.yaml, and another in my Dockerfile. I deleted the unused entrypoint and added --timeout 90 in the other.
For me, it was because I forgot to setup firewall rule on database server for my Django.
Frank's answer pointed me in the right direction. I have a Digital Ocean droplet accessing a managed Digital Ocean Postgresql database. All I needed to do was add my droplet to the database's "Trusted Sources".
(click on database in DO console, then click on settings. Edit Trusted Sources and select droplet name (click in editable area and it will be suggested to you)).
David Miller brings 15 years of experience in global economics, personal finance strategy, and market dynamics. He specializes in turning complex economic trends into actionable insights for everyday readers.
