
How Do I Remove Duplicates from a Unix File?

Contents How Do I Remove Duplicate Files in Linux? the Uniq Command Is Used to Remove Duplicate Lines from a Text File in Linux. by Default, This Command...
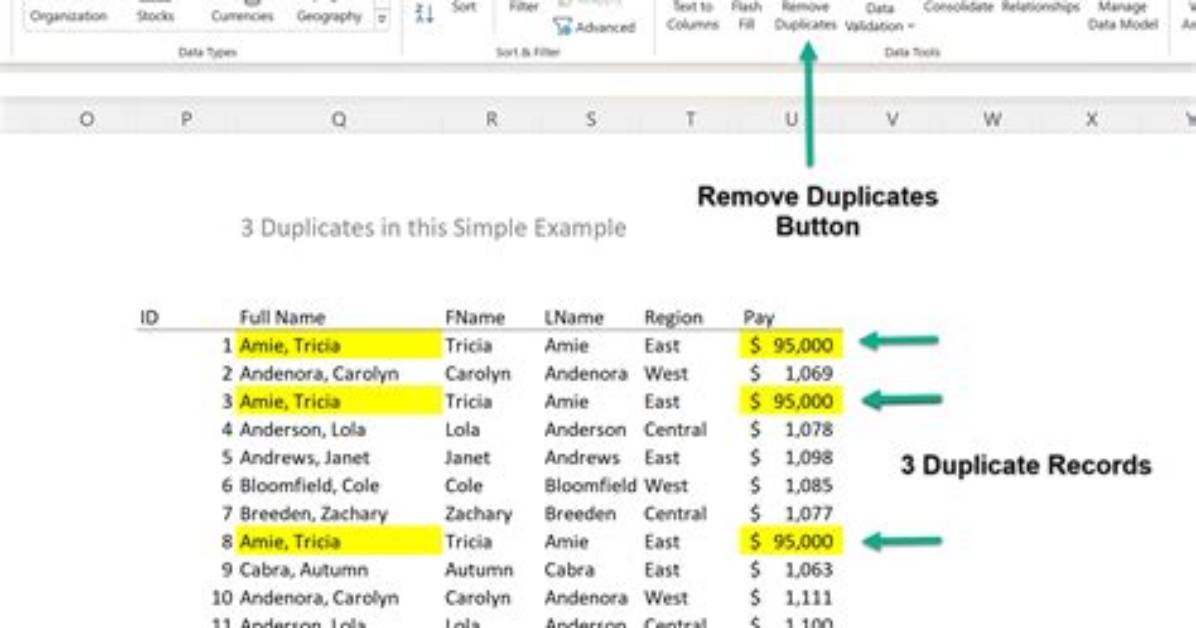
How do I remove duplicate files in Linux?
The uniq command is used to remove duplicate lines from a text file in Linux. By default, this command discards all but the first of adjacent repeated lines, so that no output lines are repeated. Optionally, it can instead only print duplicate lines.
Must Read
How can I delete duplicate records?
To remove duplicate values, click Data > Data Tools > Remove Duplicates. To highlight unique or duplicate values, use the Conditional Formatting command in the Style group on the Home tab.
Sarah Jenkins is a veteran tech journalist with over 12 years of experience covering artificial intelligence, mobile innovations, and digital ethics. Her insights have appeared in leading technology publications worldwide.
