
How Does Hive Work Hadoop

How Does Apache Hive Work? in Short, Apache Hive Translates the Input Program Written in the Hiveql (Sql-Like) Language to One or More Java Mapreduce, Tez, or...
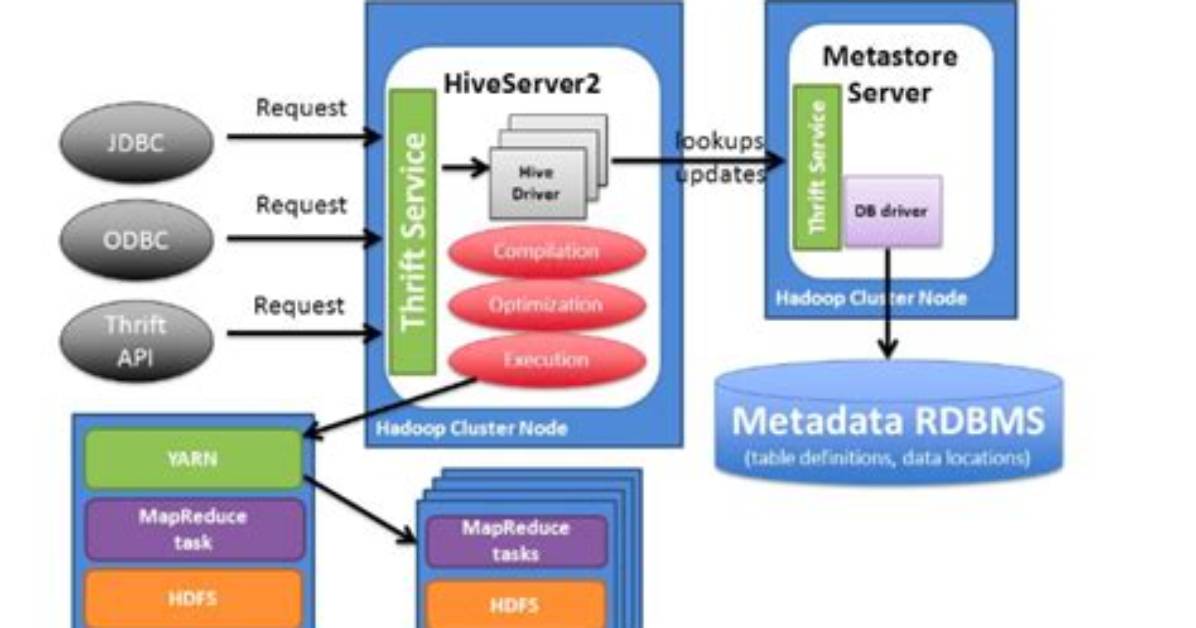
How Does Apache Hive Work? In short, Apache Hive translates the input program written in the HiveQL (SQL-like) language to one or more Java MapReduce, Tez, or Spark jobs. … Apache Hive then organizes the data into tables for the Hadoop Distributed File System HDFS) and runs the jobs on a cluster to produce an answer.
How does Hive work internally?
Hive internally uses a MapReduce framework as a defacto engine for executing the queries. MapReduce is a software framework for writing those applications that process a massive amount of data in parallel on the large clusters of commodity hardware.
Can Hive work without Hadoop?
5 Answers. To be precise, it means running Hive without HDFS from a hadoop cluster, it still need jars from hadoop-core in CLASSPATH so that hive server/cli/services can be started. btw, hive.
David Miller brings 15 years of experience in global economics, personal finance strategy, and market dynamics. He specializes in turning complex economic trends into actionable insights for everyday readers.
