
How Is Scikit-Learn Cross_Val_Predict Accuracy Score Calculated?

Does the Cross_Val_Predict (See Doc, V0.18) with K-Fold Method as Shown in the Code Below Calculate Accuracy for Each Fold and Average Them Finally or Not? Cv...
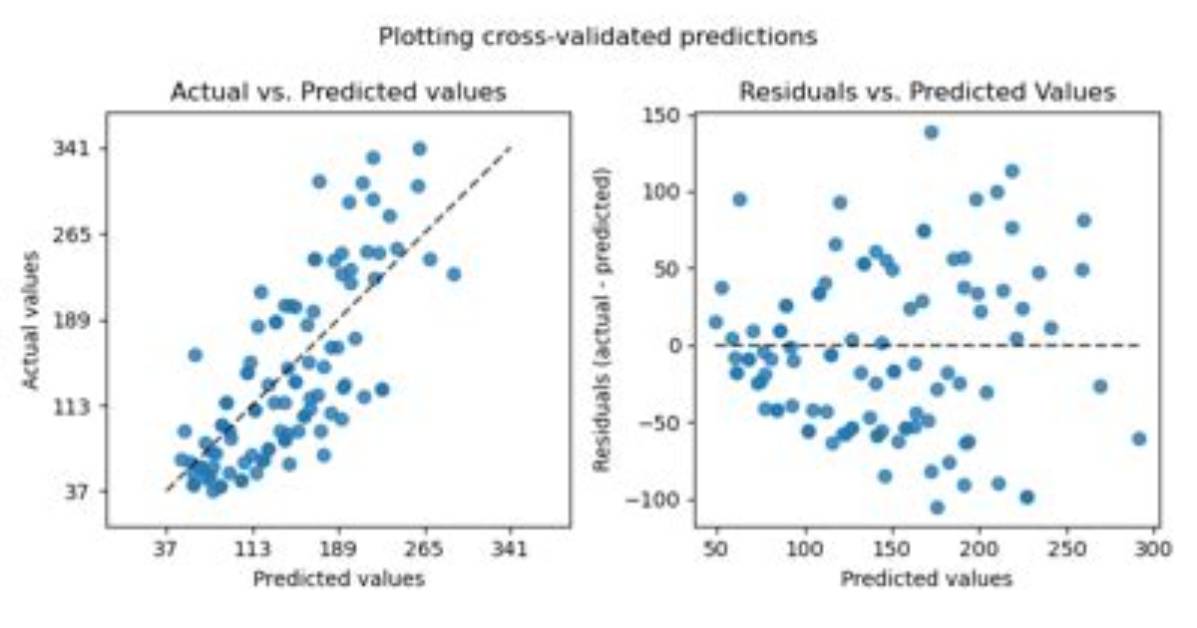
Does the cross_val_predict (see doc, v0.18) with k-fold method as shown in the code below calculate accuracy for each fold and average them finally or not?
cv = KFold(len(labels), n_folds=20)
clf = SVC()
ypred = cross_val_predict(clf, td, labels, cv=cv)
accuracy = accuracy_score(labels, ypred)
print accuracy
4 Answers
No, it does not!
According to cross validation doc page, cross_val_predict does not return any scores but only the labels based on a certain strategy which is described here:
The function cross_val_predict has a similar interface to cross_val_score, but returns, for each element in the input, the prediction that was obtained for that element when it was in the test set. Only cross-validation strategies that assign all elements to a test set exactly once can be used (otherwise, an exception is raised).
And therefore by calling accuracy_score(labels, ypred) you are just calculating accuracy scores of labels predicted by aforementioned particular strategy compared to the true labels. This again is specified in the same documentation page:
These prediction can then be used to evaluate the classifier:
predicted = cross_val_predict(clf, iris.data, iris.target, cv=10)
metrics.accuracy_score(iris.target, predicted)
Note that the result of this computation may be slightly different from those obtained using cross_val_score as the elements are grouped in different ways.
If you need accuracy scores of different folds you should try:
>>> scores = cross_val_score(clf, X, y, cv=cv)
>>> scores
array([ 0.96...,  1.  ...,  0.96...,  0.96...,  1.        ])
and then for the mean accuracy of all folds use scores.mean():
>>> print("Accuracy: %0.2f (+/- %0.2f)" % (scores.mean(), scores.std() * 2))
Accuracy: 0.98 (+/- 0.03)
How to calculate Cohen kappa coefficient and confusion matrix for each fold?
For calculating Cohen Kappa coefficient and confusion matrix I assumed you mean kappa coefficient and confusion matrix between true labels and each fold's predicted labels:
from sklearn.model_selection import KFold
from sklearn.svm.classes import SVC
from sklearn.metrics.classification import cohen_kappa_score
from sklearn.metrics import confusion_matrix

cv = KFold(len(labels), n_folds=20)
clf = SVC()
for train_index, test_index in cv.split(X):
    clf.fit(X[train_index], labels[train_index])
    ypred = clf.predict(X[test_index])
    kappa_score = cohen_kappa_score(labels[test_index], ypred)
    confusion_matrix = confusion_matrix(labels[test_index], ypred)
Maya is a hardware enthusiast who tests and reviews smart home devices, smartphones, wearables, and audio gear. She focuses on practical consumer value and build quality.
