
How to Create Surrogate Key

How Is Surrogate Key Generated? You May Construct a Knowledge Stream to Load a Desk That Has Surrogate Keys Through the Use of a Self-Referential...
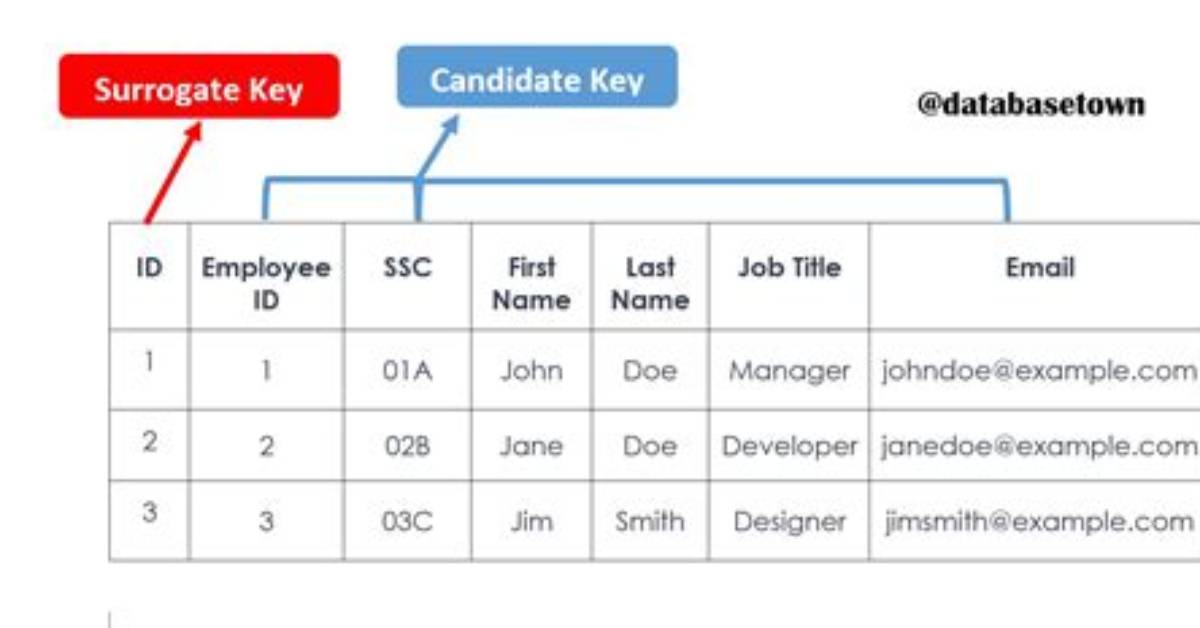
How is surrogate key generated?
You may construct a knowledge stream to load a desk that has surrogate keys through the use of a self-referential transformation to generate the values for the surrogate key subject. Within the following instance, DMSALE, a gross sales desk, is the info supply, and the extracted data are loaded right into a desk named DMREPS.
How do you create a surrogate key in hive?
To generate the surrogate key worth in HIVE, one should use “ROW_NUMBER () OVER ()” operate. When the question is run utilizing “ROW_NUMBER () OVER ()” operate, the entire knowledge set is loaded into the reminiscence.
What’s surrogate key instance?
RDBMSDatabaseMySQL. A Surrogate Key’s solely objective is to be a singular identifier in a database, for instance, incremental key, GUID, and so forth. It has. Surrogate Key has no precise that means and is used to symbolize existence.
How do you create a surrogate key in Bigquery?
Producing Surrogate Keys
- SELECT ROW_NUMBER() OVER() AS ID, * FROM `bigquery-public-data.usa_names.usa_1910_current`
- SELECT SHA256(CONCAT(state, gender, 12 months, identify)) as ID, * FROM `bigquery-public-data.usa_names.usa_1910_current`
- SELECT GENERATE_UUID() as ID, * FROM `bigquery-public-data.usa_names.usa_1910_current.
How do you generate a surrogate key in Databricks?
I used to be pondering with three approaches easy methods to generate surrogate keys when utilizing Databricks and Azure Synapse:
- Use IDENTITY-column in Azure Synapse.
- Use Databricks‘ MONOTONICALLY_INCREASING_ID-function.
- Use ROW_NUMBER performance in Databricks‘ SQL block.
How do I create a sequence quantity in spark?
choose patient_id, department_id, row_number() over (partition by department_id order by dept_id asc) as Pat_serial_Nbr from T_patient; Row_number() in Spark program is operating for greater than 4 hours and failing for 15 Billion data.
What’s SEQ in Pyspark?
pyspark.sql.features. sequence (begin, cease, step=None)[source] Generate a sequence of integers from begin to cease , incrementing by step . If step isn’t set, incrementing by 1 if begin is lower than or equal to cease , in any other case -1.
What’s sequence in spark?
Seq is a trait which represents listed sequences which can be assured immutable. You may entry parts through the use of their indexes. It maintains insertion order of parts. Sequences help a lot of strategies to seek out occurrences of parts or subsequences. It returns a listing.
How do you add row numbers in Pyspark?
So as to populate row quantity in pyspark we use row_number() Operate. row_number() operate together with partitionBy() of different column populates the row quantity by group.
What’s window in Pyspark?
Window (additionally, windowing or windowed) features carry out a calculation over a set of rows. carry out a calculation over a gaggle of rows, referred to as the Body.
How do I add a row quantity to a Dataframe?
Generate row quantity in pandas python
- Generate row quantity of the dataframe in pandas python utilizing arange() operate.
- Generate row quantity of the group.
- Generate the column which accommodates row quantity and find the column place on our alternative.
- Generate the row quantity from a selected fixed in pandas.
- Assign worth for every group in pandas python.
How do I add a row to a Dataframe in spark?
“scala spark add row to dataframe” Code Reply
- # Create laborious coded row. unknown_list = [[‘0’, ‘Unknown’]]
- # flip row into dataframe. unknown_df = spark. createDataFrame(unknown_list)
- # union with present dataframe. df = df. union(unknown_df)
How do you make a spark row?
To create a brand new Row, use RowFactory. create() in Java or Row. apply() in Scala. A Row object could be constructed by offering subject values.
How do I make a Pyspark DataFrame from a listing?
PySpark Create DataFrame from Record
- dept = [(“Finance”,10), (“Marketing”,20), (“Sales”,30), (“IT”,40) ]
- deptColumns = [“dept_name”,”dept_id”] deptDF = spark. createDataFrame(knowledge=dept, schema = deptColumns) deptDF.
- from pyspark. sql.
- # Utilizing record of Row sort from pyspark.
How do I create a DataFrame in spark?
One simple option to create Spark DataFrame manually is from an present RDD.
1. Spark Create DataFrame from RDD
- 1.1 Utilizing toDF() operate. As soon as we’ve an RDD, let’s use toDF() to create DataFrame in Spark.
- 1.2 Utilizing Spark createDataFrame() from SparkSession.
- 1.3 Utilizing createDataFrame() with the Row sort.
What’s SparkContext and Sparksession?
Spark session is a unified entry level of a spark utility from Spark 2.0. It offers a option to work together with numerous spark’s performance with a lesser variety of constructs. As a substitute of getting a spark context, hive context, SQL context, now all of it’s encapsulated in a Spark session.
What’s a spark DataFrame?
In Spark, a DataFrame is a distributed assortment of knowledge organized into named columns. It’s conceptually equal to a desk in a relational database or a knowledge body in R/Python, however with richer optimizations beneath the hood.
What’s spark SQLContext?
SQLContext is a category and is used for initializing the functionalities of Spark SQL. SparkContext class object (sc) is required for initializing SQLContext class object. By default, the SparkContext object is initialized with the identify sc when the spark-shell begins. Use the next command to create SQLContext.
Is spark SQL quicker than Hive?
Hive and Spark are each immensely in style instruments within the large knowledge world. Hive is the best choice for performing knowledge analytics on giant volumes of knowledge utilizing SQLs. Spark, alternatively, is the best choice for operating large knowledge analytics. It offers a quicker, extra trendy various to MapReduce.
How do I get SQLContext in spark shell?
SQLContext in spark–shell
You may create an SQLContext in Spark shell by passing a default SparkContext object (sc) as a parameter to the SQLContext constructor.
How do I cease spark context?
1 Reply. To cease present context you should utilize cease methodology on a given SparkContext occasion. To reuse present context or create a brand new one you should utilize SparkContex.
What occurs if we cease spark context?
1 Reply. it returns “true”. Therefore, it looks like stopping a session stops the context as nicely, i. e., the second command in my first publish is redundant. Please word that in Pyspark isStopped doesn’t appear to work: “‘SparkContext‘ object has no attribute ‘isStopped’”.
Robert Thorne covers electric vehicle innovations, autonomous driving systems, global mobility trends, and automotive engineering developments.
