
How to Extract Http Response Body from a Python Requests Call?

I'm Using the Python Requests Library. I'm Trying to Figure out How to Extract the Actual Html Body from a Response. the Code Looks a Bit Like This: R =...
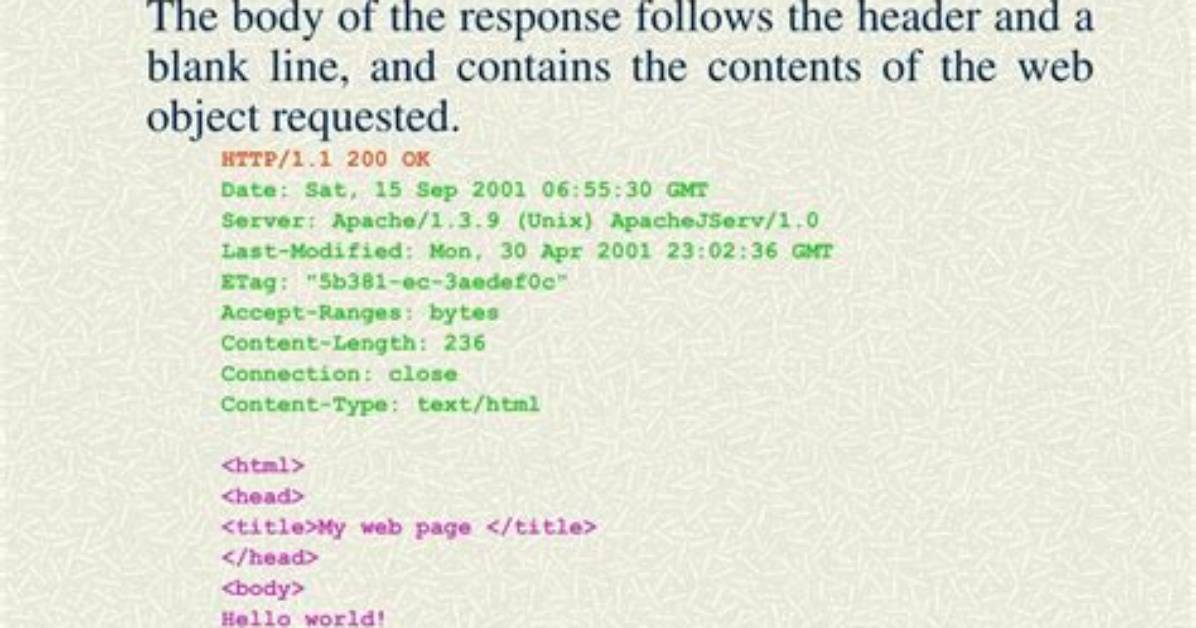
I'm using the Python requests library. I'm trying to figure out how to extract the actual HTML body from a response. The code looks a bit like this:
r = requests.get(...)
print r.content
This should indeed print lots of content, but instead prints nothing.
Any suggestions? Maybe I've misunderstood how requests.get() works?
3 Answers
Your code is correct. I tested:
r = requests.get("")
print(r.content)
And it returned plenty of content. Check the url, try "". Cheers!
You can try this method:
import requests

response = requests.get("")
response.raise_for_status()

data = response.json()
print(data)
import requests

site_request = requests.get("")

site_response = str(site_request.content)

print(site_response)
You can do it either way.
Alexander Ross has covered the video game industry for a decade, writing deep dives on game design, esports tournaments, VR developments, and gaming culture.
