
Http Get with Request Body

I'm Developing a New Restful Webservice for Our Application. When Doing a Get on Certain Entities, Clients Can Request the Contents of the Entity. If They Want...
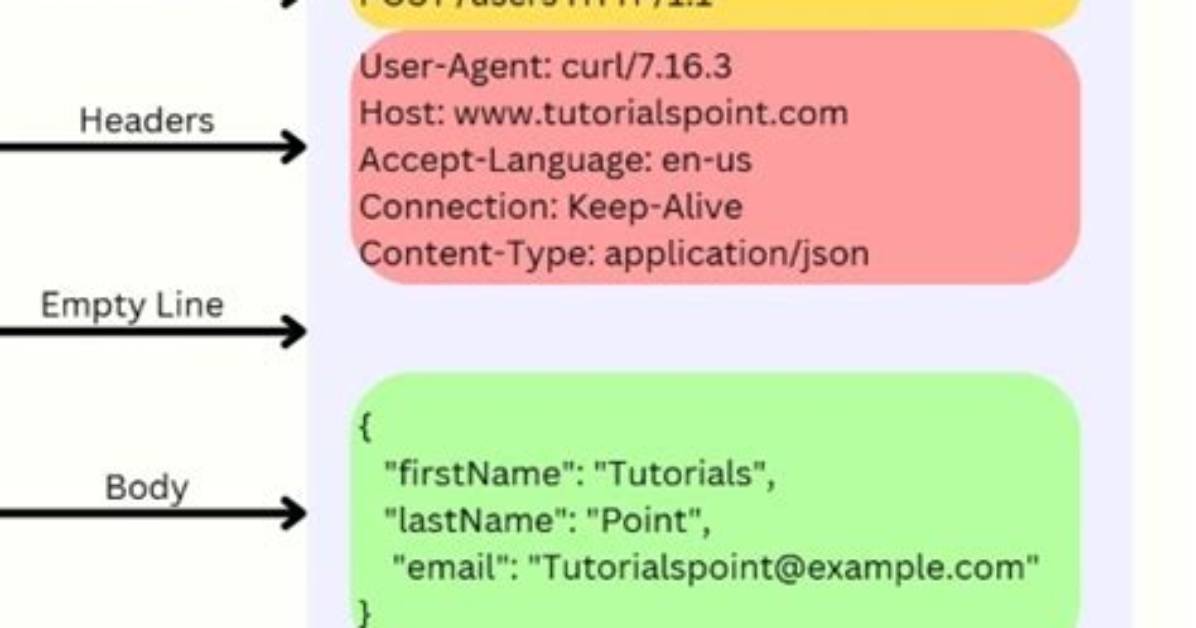
I'm developing a new RESTful webservice for our application.
When doing a GET on certain entities, clients can request the contents of the entity. If they want to add some parameters (for example sorting a list) they can add these parameters in the query string.
Alternatively I want people to be able to specify these parameters in the request body. HTTP/1.1 does not seem to explicitly forbid this. This will allow them to specify more information, might make it easier to specify complex XML requests.
My questions:
- Is this a good idea altogether?
- Will HTTP clients have issues with using request bodies within a GET request?
21 Answers
Roy Fielding's comment about including a body with a GET request.
Yes. In other words, any HTTP request message is allowed to contain a message body, and thus must parse messages with that in mind. Server semantics for GET, however, are restricted such that a body, if any, has no semantic meaning to the request. The requirements on parsing are separate from the requirements on method semantics.
So, yes, you can send a body with GET, and no, it is never useful to do so.
This is part of the layered design of HTTP/1.1 that will become clear again once the spec is partitioned (work in progress).
....Roy
Yes, you can send a request body with GET but it should not have any meaning. If you give it meaning by parsing it on the server and changing your response based on its contents, then you are ignoring this recommendation in the HTTP/1.1 spec, section 4.3:
...if the request method does not include defined semantics for an entity-body, then the message-body SHOULD be ignored when handling the request.
And the description of the GET method in the HTTP/1.1 spec, section 9.3:
The GET method means retrieve whatever information ([...]) is identified by the Request-URI.
which states that the request-body is not part of the identification of the resource in a GET request, only the request URI.
Update
The RFC2616 referenced as "HTTP/1.1 spec" is now obsolete. In 2014 it was replaced by RFCs 7230-7237. Quote "the message-body SHOULD be ignored when handling the request" has been deleted. It's now just "Request message framing is independent of method semantics, even if the method doesn't define any use for a message body" The 2nd quote "The GET method means retrieve whatever information ... is identified by the Request-URI" was deleted. - From a comment
From the HTTP 1.1 2014 Spec:
A payload within a GET request message has no defined semantics; sending a payload body on a GET request might cause some existing implementations to reject the request.
While you can do that, insofar as it isn't explicitly precluded by the HTTP specification, I would suggest avoiding it simply because people don't expect things to work that way. There are many phases in an HTTP request chain and while they "mostly" conform to the HTTP spec, the only thing you're assured is that they will behave as traditionally used by web browsers. (I'm thinking of things like transparent proxies, accelerators, A/V toolkits, etc.)
This is the spirit behind the Robustness Principle roughly "be liberal in what you accept, and conservative in what you send", you don't want to push the boundaries of a specification without good reason.
However, if you have a good reason, go for it.
You will likely encounter problems if you ever try to take advantage of caching. Proxies are not going to look in the GET body to see if the parameters have an impact on the response.
Neither restclient nor REST console support this but curl does.
The HTTP specification says in section 4.3
A message-body MUST NOT be included in a request if the specification of the request method (section 5.1.1) does not allow sending an entity-body in requests.
Section 5.1.1 redirects us to section 9.x for the various methods. None of them explicitly prohibit the inclusion of a message body. However...
Section 5.2 says
The exact resource identified by an Internet request is determined by examining both the Request-URI and the Host header field.
and Section 9.3 says
The GET method means retrieve whatever information (in the form of an entity) is identified by the Request-URI.
Which together suggest that when processing a GET request, a server is not required to examine anything other that the Request-URI and Host header field.
In summary, the HTTP spec doesn't prevent you from sending a message-body with GET but there is sufficient ambiguity that it wouldn't surprise me if it was not supported by all servers.
Elasticsearch accepts GET requests with a body. It even seems that this is the preferred way: Elasticsearch guide
Some client libraries (like the Ruby driver) can log the cry command to stdout in development mode and it is using this syntax extensively.
You can either send a GET with a body or send a POST and give up RESTish religiosity (it's not so bad, 5 years ago there was only one member of that faith -- his comments linked above).
Neither are great decisions, but sending a GET body may prevent problems for some clients -- and some servers.
Doing a POST might have obstacles with some RESTish frameworks.
Julian Reschke suggested above using a non-standard HTTP header like "SEARCH" which could be an elegant solution, except that it's even less likely to be supported.
It might be most productive to list clients that can and cannot do each of the above.
Clients that cannot send a GET with body (that I know of):
- XmlHTTPRequest Fiddler
Clients that can send a GET with body:
- most browsers
Servers & libraries that can retrieve a body from GET:
- Apache
- PHP
Servers (and proxies) that strip a body from GET:
- ?
What you're trying to achieve has been done for a long time with a much more common method, and one that doesn't rely on using a payload with GET.
You can simply build your specific search mediatype, or if you want to be more RESTful, use something like OpenSearch, and POST the request to the URI the server instructed, say /search. The server can then generate the search result or build the final URI and redirect using a 303.
This has the advantage of following the traditional PRG method, helps cache intermediaries cache the results, etc.
That said, URIs are encoded anyway for anything that is not ASCII, and so are application/x-www-form-urlencoded and multipart/form-data. I'd recommend using this rather than creating yet another custom json format if your intention is to support ReSTful scenarios.
I put this question to the IETF HTTP WG. The comment from Roy Fielding (author of http/1.1 document in 1998) was that
"... an implementation would be broken to do anything other than to parse and discard that body if received"
RFC 7213 (HTTPbis) states:
"A payload within a GET request message has no defined semantics;"
It seems clear now that the intention was that semantic meaning on GET request bodies is prohibited, which means that the request body can't be used to affect the result.
There are proxies out there that will definitely break your request in various ways if you include a body on GET.
So in summary, don't do it.
GET, with a body!?
Specification-wise you could, but, it's not a good idea to do so injudiciously, as we shall see.
RFC 7231 §4.3.1 states that a body "has no defined semantics", but that's not to say it is forbidden. If you attach a body to the request and what your server/app makes out of it is up to you. The RFC goes on to state that GET can be "a programmatic view on various database records". Obviously such view is many times tailored by a large number of input parameters, which are not always convenient or even safe to put in the query component of the request-target.
The good: I like the verbiage. It's clear that one read/get a resource without any observable side-effects on the server (the method is "safe"), and, the request can be repeated with the same intended effect regardless of the outcome of the first request (the method is "idempotent").
The bad: An early draft of HTTP/1.1 forbade GET to have a body, and - allegedly - some implementations will even up until today drop the body, ignore the body or reject the message. For example, a dumb HTTP cache may construct a cache key out of the request-target only, being oblivious to the presence or content of a body. An even dumber server could be so ignorant that it treats the body as a new request, which effectively is called "request smuggling" (which is the act of sending "a request to one device without the other device being aware of it" - source).
Due to what I believe is primarily a concern with inoperability amongst implementations, work in progress suggests to categorize a GET body as a "SHOULD NOT", "unless [the request] is made directly to an origin server that has previously indicated, in or out of band, that such a request has a purpose and will be adequately supported" (emphasis mine).
The fix: There's a few hacks that can be employed for some of the problems with this approach. For example, body-unaware caches can indirectly become body-aware simply by appending a hash derived from the body to the query component, or disable caching altogether by responding a cache-control: no-cache header from the server.
Alas when it comes to the request chain, one is often not in control of- or even aware, of all present and future HTTP intermediaries and how they will deal with a GET body. That's why this approach must be considered generally unreliable.
Marcus Vance is a cybersecurity auditor and technology writer dedicated to educating the public about online safety, data privacy regulations, enterprise security, and emerging cyber threats.
