
Introduction to Apache Flume

Flume 101 Apache Flume Reads a Data Source and Writes It to Storage at Incredibly High Volumes and Without Losing Any Events. These Data Feeds Include...
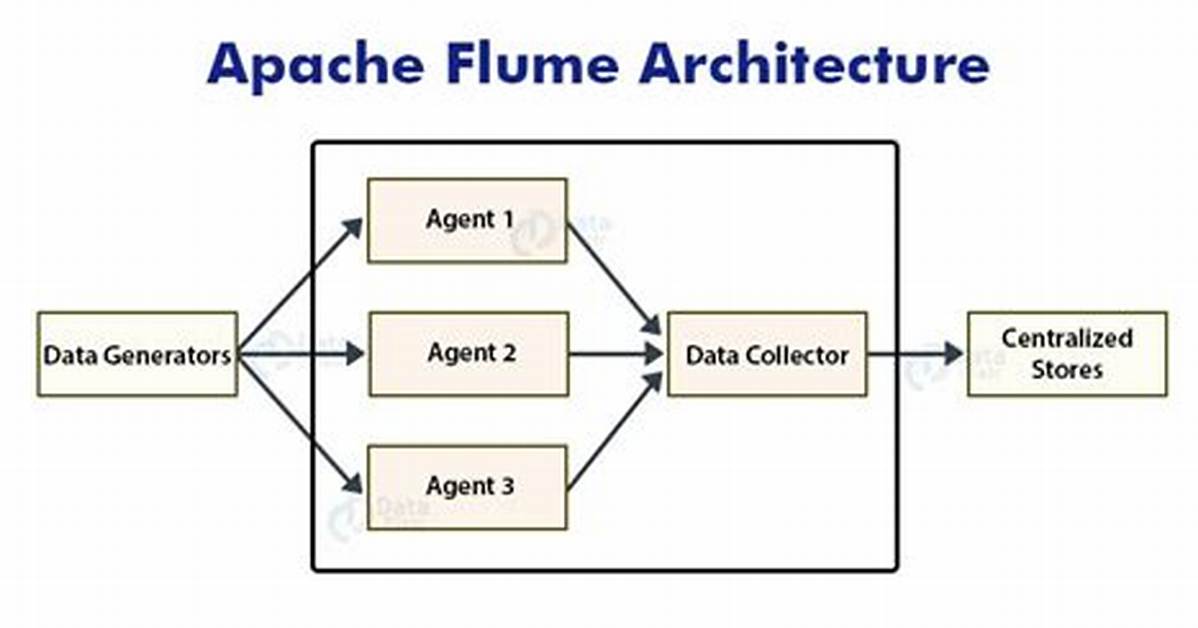
Flume 101
Apache Flume reads a data source and writes it to storage at incredibly high volumes and without losing any events. These data feeds include streaming logs, network traffic, Twitter feeds, etc. (examples below)
But it does not do data manipulation. Instead you can write it to something with the ability to do that, like Hive and, in that case, use Hive’s SQL-like commands (HQL) to process it. Or you can output it to ElasticSearch, where the data gets stored in JSON format which can be queried with Kibana. There are many other options for where to store the data.
(This article is part of our Hadoop Guide. Use the right-hand menu to navigate.)
Must Read
Installation
The installation of Flume is simple. You just download it and unzip it. There is no classpath or anything like that to set. You do not start Flume, per se. Instead you start agents, one for every data source that you want to read and save.
Marcus Vance is a cybersecurity auditor and technology writer dedicated to educating the public about online safety, data privacy regulations, enterprise security, and emerging cyber threats.
