
Introduction to Apache Pig

Apache Pig 101 Apache Pig, Developed at Yahoo, Was Written to Make It Easier to Work with Hadoop. Hadoop Was Developed by Google. Pig Lets Programmers Work...
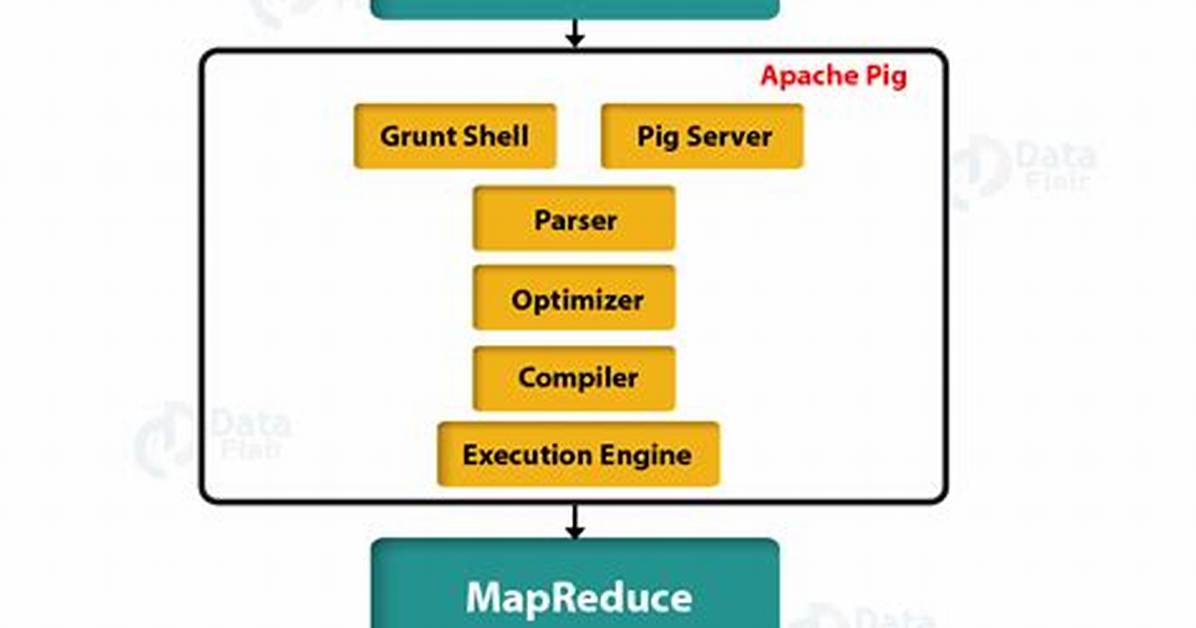
Apache Pig 101
Apache Pig, developed at Yahoo, was written to make it easier to work with Hadoop. Hadoop was developed by Google. Pig lets programmers work with Hadoop datasets using a syntax that is similar to SQL. Without Pig, programmers most commonly would use Java, the language Hadoop is written in. But Java code is inherently wordy. It would be nicer to have an easier and much shorter way to do Hadoop MapReduce operations. That is what Pig does.
But Pig is not exactly SQL. SQL programmers, in fact, will find some of its data structures a little strange.
Data in Pig is represented in data structures called tuples, with all the other Pig data structures being some variation on that. In its most basic form, a tuple is a comma delimited set of values:
(1,2,3,4,5)
(1,6,7,8,9)
And when you join two tuples, in this case on the first element, it represents the data like this:
(1,2,3,4,5,1,6,7,8,9)
Or this:
(1, {(1,2,3,4,5), (1,2,3,4,5)})
In the first case Pig has joined all the elements of two tuples into one. In the second it has put the join criteria in the first element and created a bag in the second. A bag is a collection of tuples. And individual elements are called atoms. Pig also supports maps in the format (key#value).
These odd structures leave the programmer scratching their head wondering how to unwind all of that so they can query individual atoms. We explain some of those operations below.
(This article is part of our Hadoop Guide. Use the right-hand menu to navigate.)
Using Pig and how it works
What Pig does is run MapReduce operations across datasets. MapReduce is the fundamental concept behind Hadoop and big data in general. But it means something quite different in Hadoop than, for example, Apache Spark or the Scala programming language. In Hadoop, the map operation means to split datasets into pieces and work on those pieces in parallel. Reduce means put them all back together to deliver the desired dataset. In Spark and Scala, map means to run some operation on every element on a list. Reduce means to calculate a final single value from those operations in Spark.
You start Pig in local model using:
pig -x local
Instead of just Pig:
pig
Which causes it to run in cluster (aka mapReduce) mode. Local model simulates a distributed architecture. In cluster mode, mapReduce uses Apache Yarn to run jobs on the cluster (i.e., a network of machines) and stores the resulting data in HDFS (Hadoop Distributed File System).
Elena Rostova holds a Master's degree in Public Health Journalism. She covers groundbreaking medical research, holistic wellness trends, mental health awareness, and nutritional science.
