
Pandas 'Count(Distinct)' Equivalent

I Am Using Pandas as a Database Substitute as I Have Multiple Databases (Oracle, Sql Server, Etc.), and I Am Unable to Make a Sequence of Commands to a Sql...
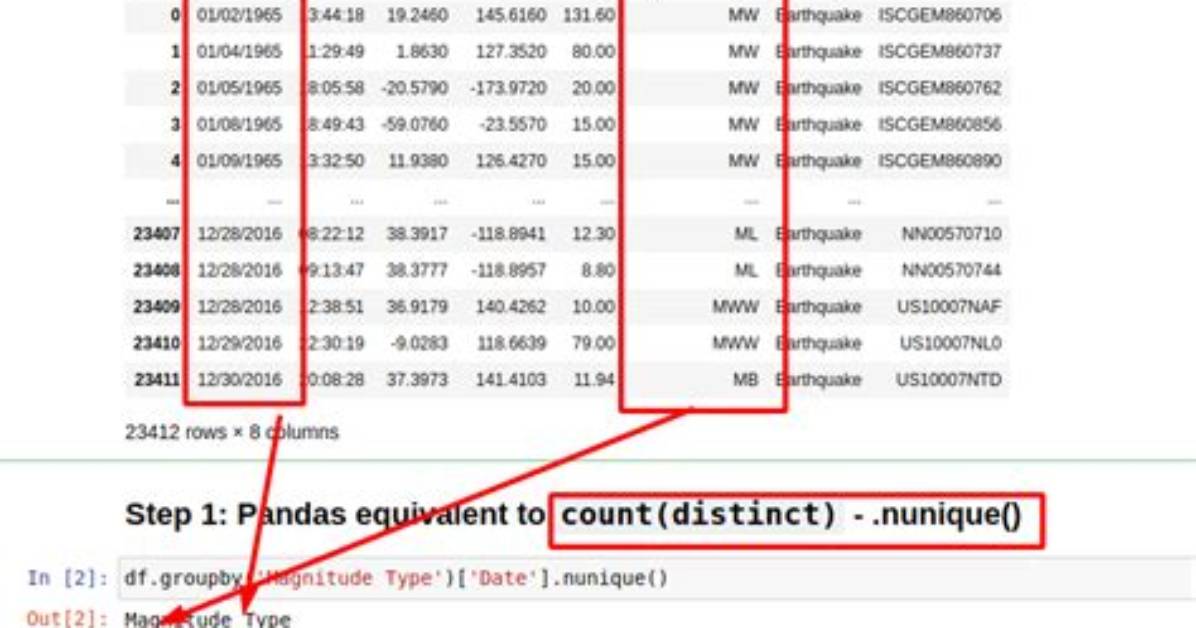
I am using Pandas as a database substitute as I have multiple databases (Oracle, SQL Server, etc.), and I am unable to make a sequence of commands to a SQL equivalent.
I have a table loaded in a DataFrame with some columns:
YEARMONTH, CLIENTCODE, SIZE, etc., etc.
In SQL, to count the amount of different clients per year would be:
SELECT count(distinct CLIENTCODE) FROM table GROUP BY YEARMONTH;
And the result would be
201301    5000
201302    13245
How can I do that in Pandas?
I believe this is what you want:
table.groupby('YEARMONTH').CLIENTCODE.nunique()
Example:
In [2]: table
Out[2]:
   CLIENTCODE  YEARMONTH
0           1     201301
1           1     201301
2           2     201301
3           1     201302
4           2     201302
5           2     201302
6           3     201302

In [3]: table.groupby('YEARMONTH').CLIENTCODE.nunique()
Out[3]:
YEARMONTH
201301       2
201302       3
Here is another method and it is much simpler. Let’s say your dataframe name is daat and the column name is YEARMONTH:
daat.YEARMONTH.value_counts()
Interestingly enough, very often len(unique()) is a few times (3x-15x) faster than nunique().
I am also using nunique but it will be very helpful if you have to use an aggregate function like 'min', 'max', 'count' or 'mean' etc.
df.groupby('YEARMONTH')['CLIENTCODE'].transform('nunique') #count(distinct)
df.groupby('YEARMONTH')['CLIENTCODE'].transform('min')     #min
df.groupby('YEARMONTH')['CLIENTCODE'].transform('max')     #max
df.groupby('YEARMONTH')['CLIENTCODE'].transform('mean')    #average
df.groupby('YEARMONTH')['CLIENTCODE'].transform('count')   #count
Distinct of column along with aggregations on other columns
To get the distinct number of values for any column (CLIENTCODE in your case), we can use nunique. We can pass the input as a dictionary in agg function, along with aggregations on other columns:
grp_df = df.groupby('YEARMONTH').agg({'CLIENTCODE': ['nunique'],
                                      'other_col_1': ['sum', 'count']})

# to flatten the multi-level columns
grp_df.columns = ["_".join(col).strip() for col in grp_df.columns.values]

# if you wish to reset the index
grp_df.reset_index(inplace=True)
Using crosstab, this will return more information than groupby nunique:
pd.crosstab(df.YEARMONTH,df.CLIENTCODE)
Out[196]:
CLIENTCODE  1  2  3
YEARMONTH
201301      2  1  0
201302      1  2  1
After a little bit of modification, it yields the result:
pd.crosstab(df.YEARMONTH,df.CLIENTCODE).ne(0).sum(1)
Out[197]:
YEARMONTH
201301    2
201302    3
dtype: int64
Here is an approach to have count distinct over multiple columns. Let's have some data:
data = {'CLIENT_CODE':[1,1,2,1,2,2,3],
        'YEAR_MONTH':[201301,201301,201301,201302,201302,201302,201302],
        'PRODUCT_CODE': [100,150,220,400,50,80,100]
       }
table = pd.DataFrame(data)
table

CLIENT_CODE YEAR_MONTH  PRODUCT_CODE
0   1       201301      100
1   1       201301      150
2   2       201301      220
3   1       201302      400
4   2       201302      50
5   2       201302      80
6   3       201302      100
Now, list the columns of interest and use groupby in a slightly modified syntax:
columns = ['YEAR_MONTH', 'PRODUCT_CODE']
table[columns].groupby(table['CLIENT_CODE']).nunique()
We obtain:
YEAR_MONTH  PRODUCT_CODE CLIENT_CODE
1           2            3
2           2            3
3           1            1
With the new Pandas version, it is easy to get as a data frame:
unique_count = pd.groupby(['YEARMONTH'], as_index=False).agg(uniq_CLIENTCODE=('CLIENTCODE', pd.Series.count))
Create a pivot table and use the nunique series function:
ID = [ 123, 123, 123, 456, 456, 456, 456, 789, 789]
domain = ['vk.com', 'vk.com', 'twitter.com', 'vk.com', 'facebook.com',
          'vk.com', 'google.com', 'twitter.com', 'vk.com']
df = pd.DataFrame({'id':ID, 'domain':domain})
fp = pd.pivot_table(data=df, index='domain', aggfunc=pd.Series.nunique)
print(fp)
Output:
               id
domain
facebook.com   1
google.com     1
twitter.com    2
vk.com         3
Now you are also able to use dplyr syntax in Python to do it:
>>> from datar.all import f, tibble, group_by, summarise, n_distinct
>>>
>>> data = tibble(
...     CLIENT_CODE=[1,1,2,1,2,2,3],
...     YEAR_MONTH=[201301,201301,201301,201302,201302,201302,201302]
... )
>>>
>>> data >> group_by(f.YEAR_MONTH) >> summarise(n=n_distinct(f.CLIENT_CODE))
   YEAR_MONTH       n
      <int64> <int64>
0      201301       2
1      201302       3
David Miller brings 15 years of experience in global economics, personal finance strategy, and market dynamics. He specializes in turning complex economic trends into actionable insights for everyday readers.
