
Pandas Read_Csv from Url

I'm Trying to Read a Csv-File from Given Url, Using Python 3. X: Import Pandas as Pd Import Requests Url = "" S = Requests. Get(Url). Content C = Pd...
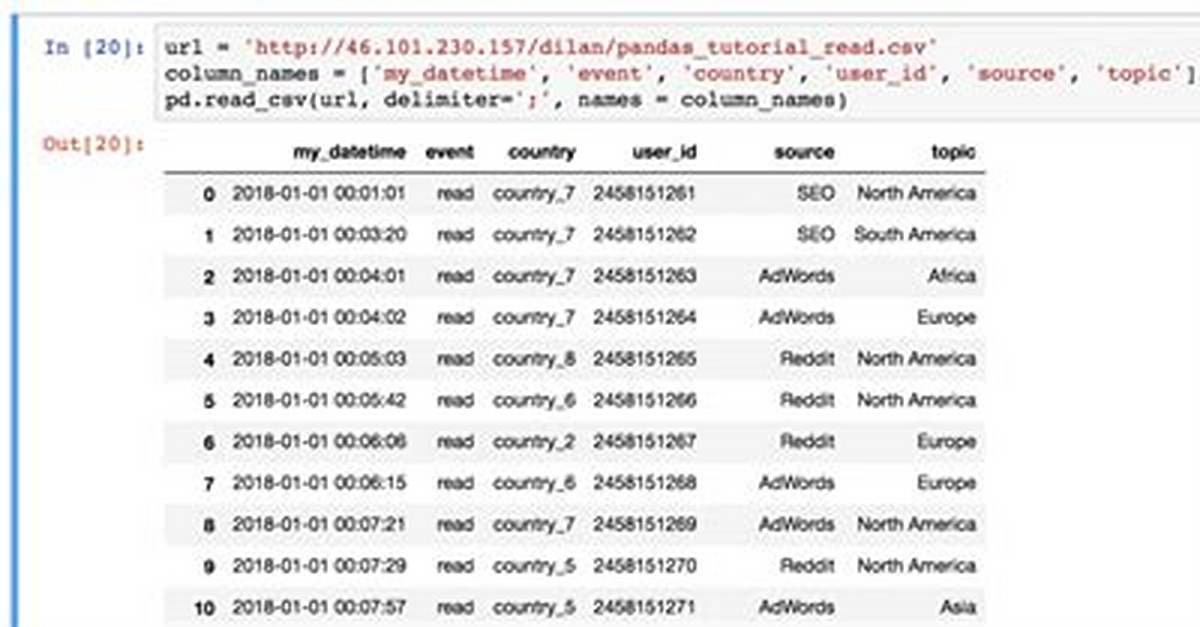
I'm trying to read a csv-file from given URL, using Python 3.x:
import pandas as pd
import requests

url = ""
s = requests.get(url).content
c = pd.read_csv(s)
I have the following error
"Expected file path name or file-like object, got <class 'bytes'> type"
How can I fix this? I'm using Python 3.4
6 Answers
In the latest version of pandas (0.19.2) you can directly pass the url
import pandas as pd

url=""
c=pd.read_csv(url)
UPDATE: From pandas 0.19.2 you can now just pass read_csv() the url directly, although that will fail if it requires authentication.
For older pandas versions, or if you need authentication, or for any other HTTP-fault-tolerant reason:
Use pandas.read_csv with a file-like object as the first argument.
If you want to read the csv from a string, you can use
io.StringIO.For the URL
, you gethtmlresponse, not raw csv; you should use the url given by theRawlink in the github page for getting raw csv response , which is
Example:
import pandas as pd
import io
import requests
url=""
s=requests.get(url).content
c=pd.read_csv(io.StringIO(s.decode('utf-8')))
Notes:
in Python 2.x, the string-buffer object was StringIO.StringIO
As I commented you need to use a StringIO object and decode i.e c=pd.read_csv(io.StringIO(s.decode("utf-8"))) if using requests, you need to decode as .content returns bytes if you used .text you would just need to pass s as is s = requests.get(url).text c = pd.read_csv(StringIO(s)).
A simpler approach is to pass the correct url of the raw data directly to read_csv, you don't have to pass a file like object, you can pass a url so you don't need requests at all:
c = pd.read_csv("")

print(c)
Output:
                              Country         Region
0                             Algeria         AFRICA
1                              Angola         AFRICA
2                               Benin         AFRICA
3                            Botswana         AFRICA
4                             Burkina         AFRICA
5                             Burundi         AFRICA
6                            Cameroon         AFRICA
..................................
From the docs:
filepath_or_buffer :
string or file handle / StringIO The string could be a URL. Valid URL schemes include http, ftp, s3, and file. For file URLs, a host is expected. For instance, a local file could be file ://localhost/path/to/table.csv
The problem you're having is that the output you get into the variable 's' is not a csv, but a html file. In order to get the raw csv, you have to modify the url to:
''
Your second problem is that read_csv expects a file name, we can solve this by using StringIO from io module. Third problem is that request.get(url).content delivers a byte stream, we can solve this using the request.get(url).text instead.
End result is this code:
from io import StringIO

import pandas as pd
import requests
url='
s=requests.get(url).text

c=pd.read_csv(StringIO(s))
output:
>>> c.head()
    Country  Region
0   Algeria  AFRICA
1    Angola  AFRICA
2     Benin  AFRICA
3  Botswana  AFRICA
4   Burkina  AFRICA
url = ""
c = pd.read_csv(url, sep = "\t")
To Import Data through URL in pandas just apply the simple below code it works actually better.
import pandas as pd
train = pd.read_table("")
train.head()
If you are having issues with a raw data then just put 'r' before URL
import pandas as pd
train = pd.read_table(r"")
train.head()
Sarah Jenkins is a veteran tech journalist with over 12 years of experience covering artificial intelligence, mobile innovations, and digital ethics. Her insights have appeared in leading technology publications worldwide.
