
Python Pandas: Simple Example of Calculating Rmse from Data Frame

Need a Simple Example of Calculating Rmse with Pandas Dataframe. Providing There Is Function That Returns in Cycle True and Predicted Value: Def Fun (Data)...
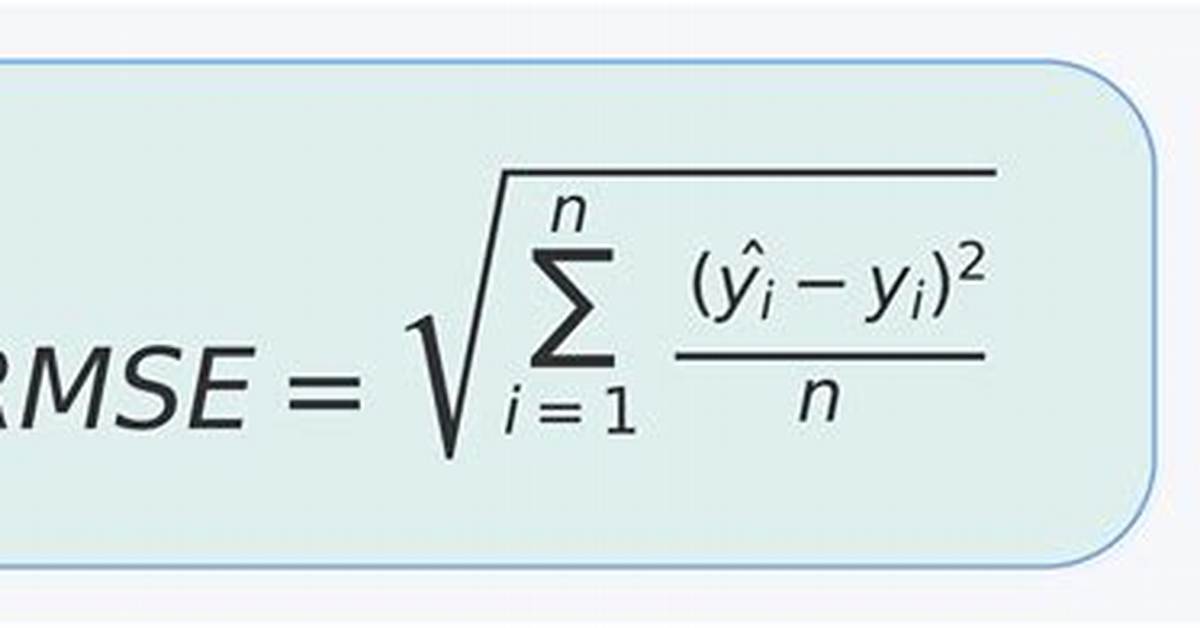
Need a simple example of calculating RMSE with Pandas DataFrame. Providing there is function that returns in cycle true and predicted value:
def fun (data):
   ...
   return trueVal, predVal

for data in set:
   fun(data)
And then some code puts these results in the following data frame where x is a real value and p is a predicted value:
In [20]: d
Out[20]: {'p': [1, 10, 4, 5, 5], 'x': [1, 2, 3, 4, 5]}

In [21]: df = pd.DataFrame(d)

In [22]: df
Out[22]:
    p  x
0   1  1
1  10  2
2   4  3
3   5  4
4   5  5
Questions:
1) How to put results from fun function in df data frame?
2) How to calculate RMSE using df data frame?
2 Answers
Question 1
This depends on the format that data is in. And I'd expect you already have your true values, so this function is just a pass through.
Question 2
With pandas
((df.p - df.x) ** 2).mean() ** .5
With numpy
(np.diff(df.values) ** 2).mean() ** .5
Question 1
I understand you already have a dataframe df. To add the new values in new rows do the following:
for data in set:

    trueVal, predVal = fun(data)

    auxDf = pd.DataFrame([[predVal, trueVal]], columns = ['p', 'x'])

    df.append(auxDf, ignore_index = True)
Question 2
To calculate RMSE using df, I recommend you to use the scikit learn function.
from sklearn.metrics import mean_squared_error
realVals = df.x
predictedVals = df.p
mse = mean_squared_error(realVals, predictedVals)
# If you want the root mean squared error
# rmse = mean_squared_error(realVals, predictedVals, squared = False)
It's very important that you don't have null values in the columns, otherwise it won't work
Alexander Ross has covered the video game industry for a decade, writing deep dives on game design, esports tournaments, VR developments, and gaming culture.
