
Regular Expressions in Notepad++ (Search and Replace)

I Have a List of Thousands of Records Within A. Txt Document. Some of Them Look Like These Records 201910031044 "00059" "11.31Ag" "Senior Champion"...
I have a list of thousands of records within a .txt document. some of them look like these records
201910031044         "00059"    "11.31AG"  "Senior Champion"
201910031044         "00060"    "GBA146"  "Junior Champion"
201910031044         "00999"    "10.12G"  "ProAM"
201910031044         "00362"    "113.1LI"  "Abcd"
Whenever a record similar to this occurs I'd like to get rid of the last words/numbers/etc in the last quotation marks (like "Senior Champion", "Junior Champion" etc. There are many possibilities here)
e.g. (before)
201910031044 "00059" "11.31AG" "Senior Champion"
after
201910031044 "00059" "11.31AG"
I tried the following regex but it wouldn't work.
Search: ^([0-9]{17,17} + "[0-9]{8,8}" + "[a-zA-Z0-9]").*$
Replace: \1 (replace string)
OK I forgot the . (dot) sign however even if I do not have a . (dot) sign it would not work. Not sure if it has anything to do when using the + sign used more than once.
4 Answers
I'd like to get rid of the last words/numbers/etc in the last quotation marks
This does the job:
- Ctrl+H
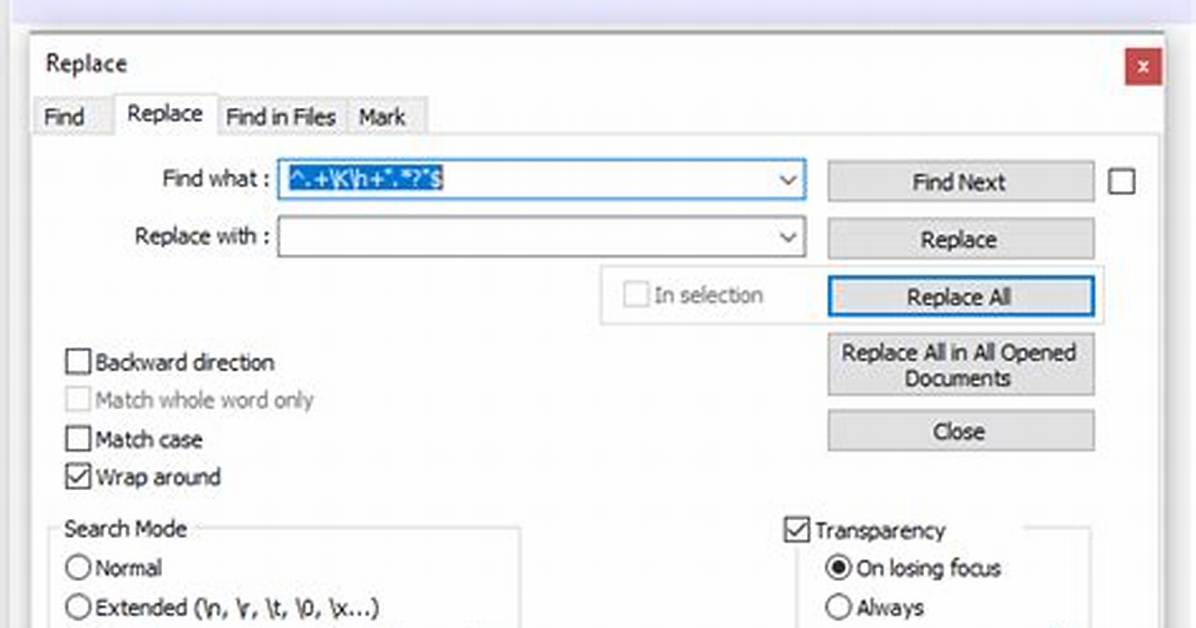
- Find what:
^.+\K\h+".*?"$ - Replace with:
LEAVE EMPTY - CHECK Wrap around
- CHECK Regular expression
- UNCHECK
. matches newline* - Replace all
Explanation:
^           # beginning of line
  .+        # 1 or more any character but newline
  \K        # forget all we have seen until this position
  \h+       # 1 or more horizontal spaces
  ".*?"     # something inside quotes
$           # end of line
Screen capture (before):
Screen capture (after):
The RegEx looks for the 4th double quote:
^(?:[^"]*\"){4}([^|]*)
You can see this demo:
You will still need to parse the lines, so probably easier opening in excel or parsing using code as a CSV.
You have a problem with the count of your characters:
- you specify that the line should start with exactly 17 digits (
[0-9]{17,17}). However, there are only 12 digits in the data201910031044.- you can specify exactly 12 digits by using
{12}or if it could be 12-17, then{12,17}. I'll assume exactly 12 based on the current data.
- you can specify exactly 12 digits by using
- similarly, for the second column you specify that it's exactly 8 digits surrounded by quotes (
"[0-9]{8,8}") but it only has 5 digits surrounded by quotes.- again, you can specify exactly 5 with
{5}or 5-8 with{5,8}. I will assume exactly 5.
- again, you can specify exactly 5 with
- finally, there is no quantifier for the final field, so the regex tries to match exactly one character that is a letter or a number surrounded by quotes
"[a-zA-Z0-9]".- I'm not sure if there is any limit on the number of characters, so I would go with one or more using
+as quantifier"[a-zA-Z0-9]+"- if you can have zero or more, then you can use*, or if it's any other count from m to n, then you can use{m,n}as before.
- I'm not sure if there is any limit on the number of characters, so I would go with one or more using
Not a character count problem but the final column can also have dots but the regex doesn't account for. You can just add . inside the square brackets and it will only match dot characters. It's usually used as a wildcard but it loses its special meaning inside a character class ([]), so you get "[a-zA-Z0-9.]+"
Putting it all together, you get
Search: ^([0-9]{12} + "[0-9]{5}" + "[a-zA-Z0-9.]+").*$
Replace: \1
Which will get rid of anything after the third field in Notepad++.
This can be shortened a bit by using \d instead of [0-9] for digits and \s+ for whitespace instead of +. As a benefit, \s will also match other whitespace like tabs, so you don't have to manually account for those. This leads to
Search: ^(\d{12}\s+"\d{5}"\s+"[a-zA-Z0-9.]+").*$
Replace: \1
If you want to get rid of the last words/numbers/etc in the last quotation marks you could capture in a group what is before that and match the last quotation marks and everything between it to remove it using a negated character class.
If what is between the values can be spaces or tabs, you could use [ \t]+ to match those (using \s could also match a newline)
Note that {17,17} and {8,8} may also be written as {17} and {8} which in this case should be {12} and {5}
^([0-9]{12}[ \t]+"[0-9]{5}"[ \t]+"[a-zA-Z0-9.]+")[ \t]{2,}"[^"\r\n]+"
In parts
^Start of string(Capture group 1[0-9]{12}[ \t]+Match 12 digits and 1+ spaces or tabs"[0-9]{5}"[ \t]+Match 5 digits between"and 1+ spaces or tabs"[a-zA-Z0-9.]+"Match 1+ times any of the listed between"
)Close group[ \t]{2,}Match 1+ times"[^"\r\n]+"
In the replacement use group 1 $1
Before
After
Chloe Bennett explores the intersection of pop culture, streaming entertainment, digital trends, and contemporary lifestyle. Her weekly commentary reaches thousands of culture enthusiasts.
