
Scikit-Learn Gridsearch Giving "Valueerror: Multiclass Format Is Not Supported" Error

I'm Trying to Use Gridsearch for Parameter Estimation of Linearsvc() as Follows - Clf_Svm = Linearsvc() Params = { 'C': [0.5, 1.0, 1.5], 'Tol': [1E-3, 1E-4...
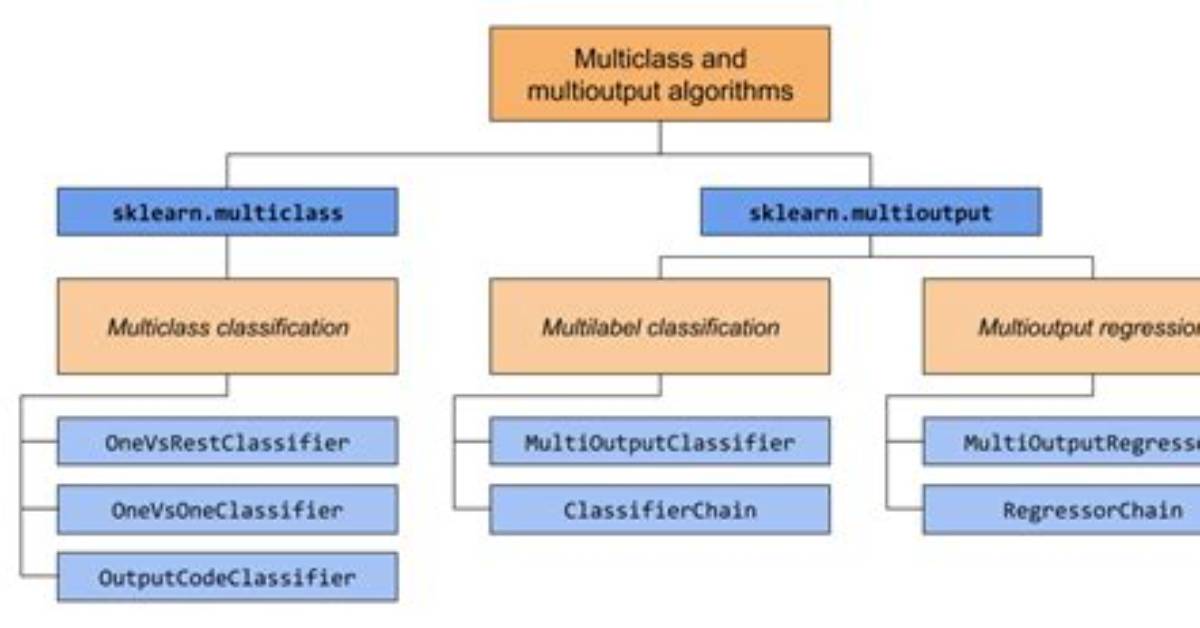
I'm trying to use GridSearch for parameter estimation of LinearSVC() as follows -
clf_SVM = LinearSVC()
params = {
          'C': [0.5, 1.0, 1.5],
          'tol': [1e-3, 1e-4, 1e-5],
          'multi_class': ['ovr', 'crammer_singer'],
          }
gs = GridSearchCV(clf_SVM, params, cv=5, scoring='roc_auc')
gs.fit(corpus1, y)
corpus1 has shape (1726, 7001) and y has shape (1726,)
This is a multiclass classification, and y has values from 0 to 3, both inclusive, i.e. there are four classes.
But this is giving me the following error -
---------------------------------------------------------------------------
ValueError                                Traceback (most recent call last)
<ipython-input-220-0c627bda0543> in <module>()
      5           }
      6 gs = GridSearchCV(clf_SVM, params, cv=5, scoring='roc_auc')
----> 7 gs.fit(corpus1, y)

/usr/local/lib/python2.7/dist-packages/sklearn/grid_search.pyc in fit(self, X, y)
    594
    595         """
--> 596         return self._fit(X, y, ParameterGrid(self.param_grid))
    597
    598

/usr/local/lib/python2.7/dist-packages/sklearn/grid_search.pyc in _fit(self, X, y, parameter_iterable)
    376                                     train, test, self.verbose, parameters,
    377                                     self.fit_params, return_parameters=True)
--> 378             for parameters in parameter_iterable
    379             for train, test in cv)
    380

/usr/local/lib/python2.7/dist-packages/sklearn/externals/joblib/parallel.pyc in __call__(self, iterable)
    651             self._iterating = True
    652             for function, args, kwargs in iterable:
--> 653                 self.dispatch(function, args, kwargs)
    654
    655             if pre_dispatch == "all" or n_jobs == 1:

/usr/local/lib/python2.7/dist-packages/sklearn/externals/joblib/parallel.pyc in dispatch(self, func, args, kwargs)
    398         """
    399         if self._pool is None:
--> 400             job = ImmediateApply(func, args, kwargs)
    401             index = len(self._jobs)
    402             if not _verbosity_filter(index, self.verbose):

/usr/local/lib/python2.7/dist-packages/sklearn/externals/joblib/parallel.pyc in __init__(self, func, args, kwargs)
    136         # Don't delay the application, to avoid keeping the input
    137         # arguments in memory
--> 138         self.results = func(*args, **kwargs)
    139
    140     def get(self):

/usr/local/lib/python2.7/dist-packages/sklearn/cross_validation.pyc in _fit_and_score(estimator, X, y, scorer, train, test, verbose, parameters, fit_params, return_train_score, return_parameters)
   1238     else:
   1239         estimator.fit(X_train, y_train, **fit_params)
-> 1240     test_score = _score(estimator, X_test, y_test, scorer)
   1241     if return_train_score:
   1242         train_score = _score(estimator, X_train, y_train, scorer)

/usr/local/lib/python2.7/dist-packages/sklearn/cross_validation.pyc in _score(estimator, X_test, y_test, scorer)
   1294         score = scorer(estimator, X_test)
   1295     else:
-> 1296         score = scorer(estimator, X_test, y_test)
   1297     if not isinstance(score, numbers.Number):
   1298         raise ValueError("scoring must return a number, got %s (%s) instead."

/usr/local/lib/python2.7/dist-packages/sklearn/metrics/scorer.pyc in __call__(self, clf, X, y)
    136         y_type = type_of_target(y)
    137         if y_type not in ("binary", "multilabel-indicator"):
--> 138             raise ValueError("{0} format is not supported".format(y_type))
    139
    140         try:

ValueError: multiclass format is not supported
5 Answers
Remove scoring='roc_auc' and it will work as roc_auc curve does not support categorical data.
from:
"Note: this implementation is restricted to the binary classification task or multilabel classification task in label indicator format."
try:
from sklearn import preprocessing
y = preprocessing.label_binarize(y, classes=[0, 1, 2, 3])
before you train. this will perform a "one-hot" encoding of your y.
As it has been pointed out, you must first binarize y
y = label_binarize(y, classes=[0, 1, 2, 3])
and then use a multiclass learning algorithm like OneVsRestClassifier or OneVsOneClassifier. For example:
clf_SVM = OneVsRestClassifier(LinearSVC())
params = {
      'estimator__C': [0.5, 1.0, 1.5],
      'estimator__tol': [1e-3, 1e-4, 1e-5],
      }
gs = GridSearchCV(clf_SVM, params, cv=5, scoring='roc_auc')
gs.fit(corpus1, y)
For multiclass classification you have to specify some params in roc_auc_score function: multi_class and average (optionally). See docs.
But how one could place these params in GridSearchCV? For these purposes, make_scorer function should be used.
multi_roc = make_scorer(roc_auc_score, average='weighted', multi_class='ovr', needs_proba=True)
searcher = GridSearchCV(LogisticRegression(n_jobs=1), params, scoring=multi_roc, cv=skf, verbose=3, n_jobs=16)
You can directly use to_categorical rather than preprocessing.label_binarize() depending on your problem. The problem is actually from using scoring=roc_auc. Note that roc_auc does not support categorical data.
Maya is a hardware enthusiast who tests and reviews smart home devices, smartphones, wearables, and audio gear. She focuses on practical consumer value and build quality.
