
Spark Error: Executor. Coarsegrainedexecutorbackend: Received Signal Term

I Am Working with Following Spark Config maxCores = 5 driverMemory=2g executorMemory=17g executorInstances=100 Issue: out of 100 Executors, My Job Ends up with...
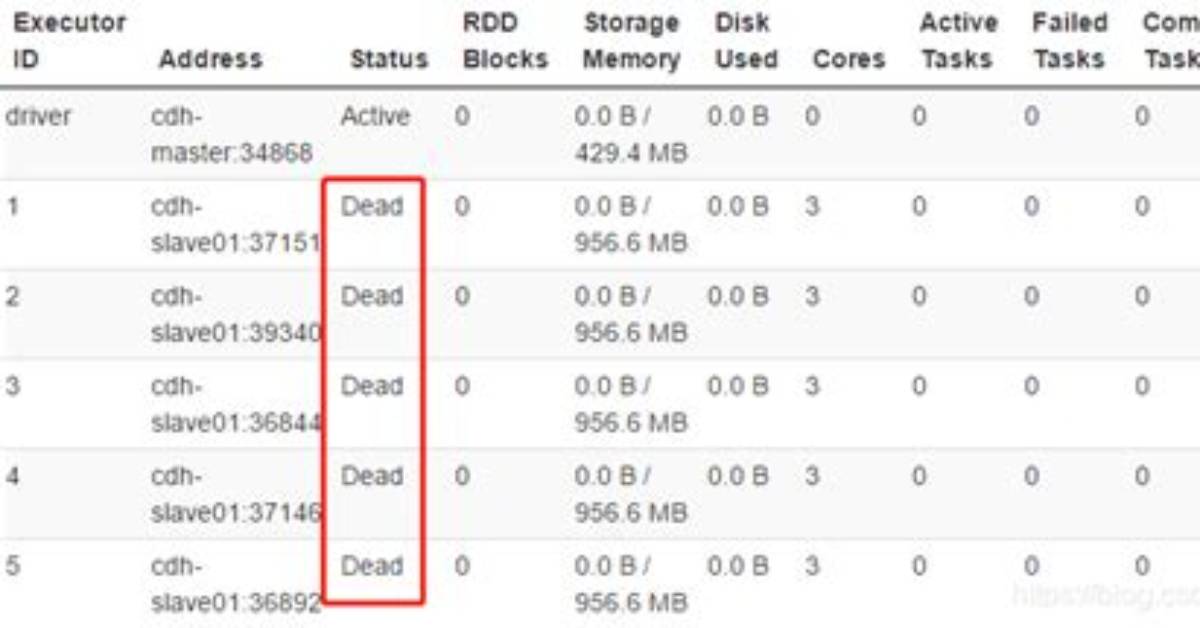
I am working with following spark config
maxCores = 5
 driverMemory=2g
 executorMemory=17g
 executorInstances=100
Issue: Out of 100 Executors, My job ends up with only 10 active executors, nonetheless enough memory is available. Even tried setting the executors to 250 only 10 remains active.All I am trying to do is loading a mulitpartition hive table and doing df.count over it.
Please help me understanding the issue causing the executors kill
17/12/20 11:08:21 ERROR executor.CoarseGrainedExecutorBackend: RECEIVED SIGNAL TERM
17/12/20 11:08:21 INFO storage.DiskBlockManager: Shutdown hook called
17/12/20 11:08:21 INFO util.ShutdownHookManager: Shutdown hook called
Not sure why yarn is killing my executors.
3 Answers
I faced a similar issue where the investigation of the NodeManager-Logs lead me to the root cause. You can access them via the Web-interface
nodeManagerAddress:PORT/logs
The PORT is specified in the yarn-site.xml under yarn.nodemanager.webapp.address. (default: 8042)
My Investigation-Workflow:
- Collect logs (yarn logs ... command)
- Identify node and container (in these logs) emitting the error
- Search the NodeManager-logs by Timestamp of the error for a root cause
Btw: you can access the aggregated collection (xml) of all configurations affecting a node at the same port with:
nodeManagerAdress:PORT/conf
I believe this issue has more to do with the memory and the dynamic time allocations on executor/container levels. Make sure you can change the config params on executor/container level.
One of the ways you can resolve this issue is by changing this config value either on your spark-shell or spark job.
spark.dynamicAllocation.executorIdleTimeout
This thread has more detailed information on how to resolve this issue which worked for me:
I had the same issue, my spark job was using only 1 task node and killing the other provisioned nodes. This also happened when switching to EMR Serverless, my job was being run on only one "thread". Please see below as it fixed it for me:
spark-submit \
--name KSSH-0.3 \
--class com.jiuye.KSSH     \
--master yarn     \
--deploy-mode cluster     \
--driver-memory 2g     \
--executor-memory 2g     \
--executor-cores   1   \
--num-executors 8 \
--jars $(echo /opt/software/spark2.1.1/spark_on_yarn/libs/*.jar | tr ' ' ',') \
--conf "spark.ui.showConsoleProgress=false" \
--conf "spark.yarn.am.memory=1024m" \
--conf "spark.yarn.am.memoryOverhead=1024m" \
--conf "spark.yarn.driver.memoryOverhead=1024m" \
--conf "spark.yarn.executor.memoryOverhead=1024m" \
--conf "spark.yarn.am.extraJavaOptions=-XX:+UseG1GC -XX:MaxGCPauseMillis=300 -XX:InitiatingHeapOccupancyPercent=50 -XX:G1ReservePercent=20 -XX:+DisableExplicitGC -Dcdh.version=5.12.0" \
--conf "spark.driver.extraJavaOptions=-XX:+UseG1GC -XX:MaxGCPauseMillis=300 -XX:InitiatingHeapOccupancyPercent=50 -XX:G1ReservePercent=20 -XX:+DisableExplicitGC -Dcdh.version=5.12.0" \
--conf "spark.executor.extraJavaOptions=-XX:+UseG1GC -XX:MaxGCPauseMillis=300 -XX:InitiatingHeapOccupancyPercent=50 -XX:G1ReservePercent=20 -XX:+DisableExplicitGC -Dcdh.version=5.12.0" \
--conf "spark.streaming.backpressure.enabled=true" \
--conf "spark.streaming.kafka.maxRatePerPartition=1250" \
--conf "spark.locality.wait=1s" \
--conf "spark.shuffle.consolidateFiles=true" \

--conf "spark.executor.heartbeatInterval=360000" \
--conf "spark.network.timeout=420000" \

--conf "spark.serializer=org.apache.spark.serializer.KryoSerializer" \
--conf "spark.hadoop.fs.hdfs.impl.disable.cache=true" \
/opt/software/spark2.1.1/spark_on_yarn/KSSH-0.3.jarMaya is a hardware enthusiast who tests and reviews smart home devices, smartphones, wearables, and audio gear. She focuses on practical consumer value and build quality.
