
Sql Rank() Versus Row_Number()

I'm Confused About the Differences Between These. Running the Following Sql Gets Me Two Idential Result Sets. Can Someone Please Explain the Differences?...
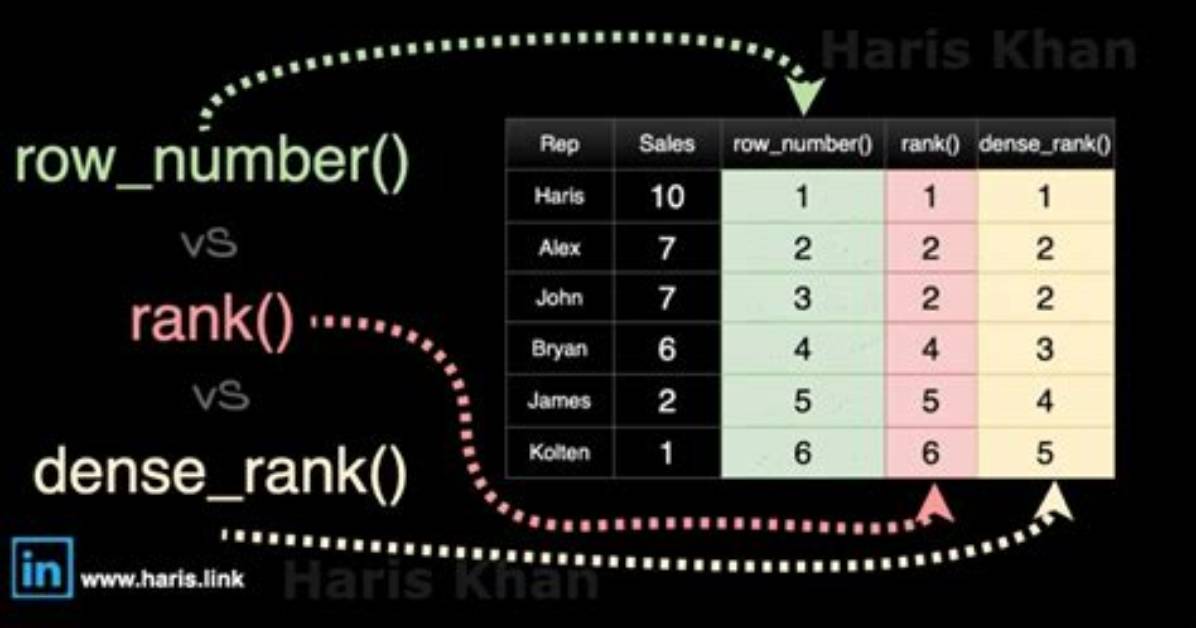
I'm confused about the differences between these. Running the following SQL gets me two idential result sets. Can someone please explain the differences?
SELECT ID, [Description], RANK()       OVER(PARTITION BY StyleID ORDER BY ID) as 'Rank'      FROM SubStyle
SELECT ID, [Description], ROW_NUMBER() OVER(PARTITION BY StyleID ORDER BY ID) as 'RowNumber' FROM SubStyle
8 Answers
You will only see the difference if you have ties within a partition for a particular ordering value.
RANK and DENSE_RANK are deterministic in this case, all rows with the same value for both the ordering and partitioning columns will end up with an equal result, whereas ROW_NUMBER will arbitrarily (non deterministically) assign an incrementing result to the tied rows.
Example: (All rows have the same StyleID so are in the same partition and within that partition the first 3 rows are tied when ordered by ID)
WITH T(StyleID, ID)
     AS (SELECT 1,1 UNION ALL
         SELECT 1,1 UNION ALL
         SELECT 1,1 UNION ALL
         SELECT 1,2)
SELECT *,
       RANK() OVER(PARTITION BY StyleID ORDER BY ID)       AS 'RANK',
       ROW_NUMBER() OVER(PARTITION BY StyleID ORDER BY ID) AS 'ROW_NUMBER',
       DENSE_RANK() OVER(PARTITION BY StyleID ORDER BY ID) AS 'DENSE_RANK'
FROM   T
Returns
StyleID     ID       RANK      ROW_NUMBER      DENSE_RANK
----------- -------- --------- --------------- ----------
1           1        1         1               1
1           1        1         2               1
1           1        1         3               1
1           2        4         4               2
You can see that for the three identical rows the ROW_NUMBER increments, the RANK value remains the same then it leaps to 4. DENSE_RANK also assigns the same rank to all three rows but then the next distinct value is assigned a value of 2.
ROW_NUMBER : Returns a unique number for each row starting with 1. For rows that have duplicate values,numbers are arbitarily assigned.
Rank : Assigns a unique number for each row starting with 1,except for rows that have duplicate values,in which case the same ranking is assigned and a gap appears in the sequence for each duplicate ranking.
This article covers an interesting relationship between ROW_NUMBER() and DENSE_RANK() (the RANK() function is not treated specifically). When you need a generated ROW_NUMBER() on a SELECT DISTINCT statement, the ROW_NUMBER() will produce distinct values before they are removed by the DISTINCT keyword. E.g. this query
SELECT DISTINCT
  v,
  ROW_NUMBER() OVER (ORDER BY v) row_number
FROM t
ORDER BY v, row_number
... might produce this result (DISTINCT has no effect):
+---+------------+
| V | ROW_NUMBER |
+---+------------+
| a |          1 |
| a |          2 |
| a |          3 |
| b |          4 |
| c |          5 |
| c |          6 |
| d |          7 |
| e |          8 |
+---+------------+
Whereas this query:
SELECT DISTINCT
  v,
  DENSE_RANK() OVER (ORDER BY v) row_number
FROM t
ORDER BY v, row_number
... produces what you probably want in this case:
+---+------------+
| V | ROW_NUMBER |
+---+------------+
| a |          1 |
| b |          2 |
| c |          3 |
| d |          4 |
| e |          5 |
+---+------------+
Note that the ORDER BY clause of the DENSE_RANK() function will need all other columns from the SELECT DISTINCT clause to work properly.
The reason for this is that logically, window functions are calculated before DISTINCT is applied.
All three functions in comparison
Using PostgreSQL / Sybase / SQL standard syntax (WINDOW clause):
SELECT
  v,
  ROW_NUMBER() OVER (window) row_number,
  RANK()       OVER (window) rank,
  DENSE_RANK() OVER (window) dense_rank
FROM t
WINDOW window AS (ORDER BY v)
ORDER BY v
... you'll get:
+---+------------+------+------------+
| V | ROW_NUMBER | RANK | DENSE_RANK |
+---+------------+------+------------+
| a |          1 |    1 |          1 |
| a |          2 |    1 |          1 |
| a |          3 |    1 |          1 |
| b |          4 |    4 |          2 |
| c |          5 |    5 |          3 |
| c |          6 |    5 |          3 |
| d |          7 |    7 |          4 |
| e |          8 |    8 |          5 |
+---+------------+------+------------+
Simple query without partition clause:
select
    sal,
    RANK() over(order by sal desc) as Rank,
    DENSE_RANK() over(order by sal desc) as DenseRank,
    ROW_NUMBER() over(order by sal desc) as RowNumber
from employee
Output:
    --------|-------|-----------|----------
    sal     |Rank   |DenseRank  |RowNumber
    --------|-------|-----------|----------
    5000    |1      |1          |1
    3000    |2      |2          |2
    3000    |2      |2          |3
    2975    |4      |3          |4
    2850    |5      |4          |5
    --------|-------|-----------|----------
Quite a bit:
The rank of a row is one plus the number of ranks that come before the row in question.
Row_number is the distinct rank of rows, without any gap in the ranking.
Look this example.
CREATE TABLE [dbo].#TestTable(
    [id] [int] NOT NULL,
    [create_date] [date] NOT NULL,
    [info1] [varchar](50) NOT NULL,
    [info2] [varchar](50) NOT NULL,
)
Insert some data
INSERT INTO dbo.#TestTable (id, create_date, info1, info2)
VALUES (1, '1/1/09', 'Blue', 'Green')
INSERT INTO dbo.#TestTable (id, create_date, info1, info2)
VALUES (1, '1/2/09', 'Red', 'Yellow')
INSERT INTO dbo.#TestTable (id, create_date, info1, info2)
VALUES (1, '1/3/09', 'Orange', 'Purple')
INSERT INTO dbo.#TestTable (id, create_date, info1, info2)
VALUES (2, '1/1/09', 'Yellow', 'Blue')
INSERT INTO dbo.#TestTable (id, create_date, info1, info2)
VALUES (2, '1/5/09', 'Blue', 'Orange')
INSERT INTO dbo.#TestTable (id, create_date, info1, info2)
VALUES (3, '1/2/09', 'Green', 'Purple')
INSERT INTO dbo.#TestTable (id, create_date, info1, info2)
VALUES (3, '1/8/09', 'Red', 'Blue')
Repeat same Values for 1
INSERT INTO dbo.#TestTable (id, create_date, info1, info2) VALUES (1, '1/1/09', 'Blue', 'Green')
Look All
SELECT * FROM #TestTable
Look your results
SELECT Id,
    create_date,
    info1,
    info2,
    ROW_NUMBER() OVER (PARTITION BY Id ORDER BY create_date DESC) AS RowId,
    RANK() OVER(PARTITION BY Id ORDER BY create_date DESC)    AS [RANK]
FROM #TestTable
Need to understand the different
I haven't done anything with rank, but I discovered this today with row_number().
select item, name, sold, row_number() over(partition by item order by sold) as row from table_name
This will result in some repeating row numbers since in my case each name holds all items. Each item will be ordered by how many were sold.
+--------+------+-----+----+
|glasses |store1|  30 | 1  |
|glasses |store2|  35 | 2  |
|glasses |store3|  40 | 3  |
|shoes   |store2|  10 | 1  |
|shoes   |store1|  20 | 2  |
|shoes   |store3|  22 | 3  |
+--------+------+-----+----+
Also, pay attention to ORDER BY in PARTITION (Standard AdventureWorks db is used for example) when using RANK.
SELECT as1.SalesOrderID, as1.SalesOrderDetailID, RANK() OVER (PARTITION BY as1.SalesOrderID ORDER BY as1.SalesOrderID ) ranknoequal , RANK() OVER (PARTITION BY as1.SalesOrderID ORDER BY as1.SalesOrderDetailId ) ranknodiff FROM Sales.SalesOrderDetail as1 WHERE SalesOrderId = 43659 ORDER BY SalesOrderDetailId;
Gives result:
SalesOrderID SalesOrderDetailID rank_same_as_partition rank_salesorderdetailid43659 1 1 1
43659 2 1 2
43659 3 1 3
43659 4 1 4
43659 5 1 5
43659 6 1 6
43659 7 1 7
43659 8 1 8
43659 9 1 9
43659 10 1 10
43659 11 1 11
43659 12 1 12
But if change order by to (use OrderQty :
SELECT as1.SalesOrderID, as1.OrderQty, RANK() OVER (PARTITION BY as1.SalesOrderID ORDER BY as1.SalesOrderID ) ranknoequal , RANK() OVER (PARTITION BY as1.SalesOrderID ORDER BY as1.OrderQty ) rank_orderqty FROM Sales.SalesOrderDetail as1 WHERE SalesOrderId = 43659 ORDER BY OrderQty;
Gives:
SalesOrderID OrderQty rank_salesorderid rank_orderqty43659 1 1 1
43659 1 1 1
43659 1 1 1
43659 1 1 1
43659 1 1 1
43659 1 1 1
43659 2 1 7
43659 2 1 7
43659 3 1 9
43659 3 1 9
43659 4 1 11
43659 6 1 12
Notice how the Rank changes when we use OrderQty (rightmost column second table) in ORDER BY and how it changes when we use SalesOrderDetailID (rightmost column first table) in ORDER BY.
Chloe Bennett explores the intersection of pop culture, streaming entertainment, digital trends, and contemporary lifestyle. Her weekly commentary reaches thousands of culture enthusiasts.
