
Stratified Sampling with Pyspark

I Have a Spark Dataframe That Has One Column That Has Lots of Zeros and Very Few Ones (Only 0.01% of Ones). I'd Like to Take a Random Subsample but a...
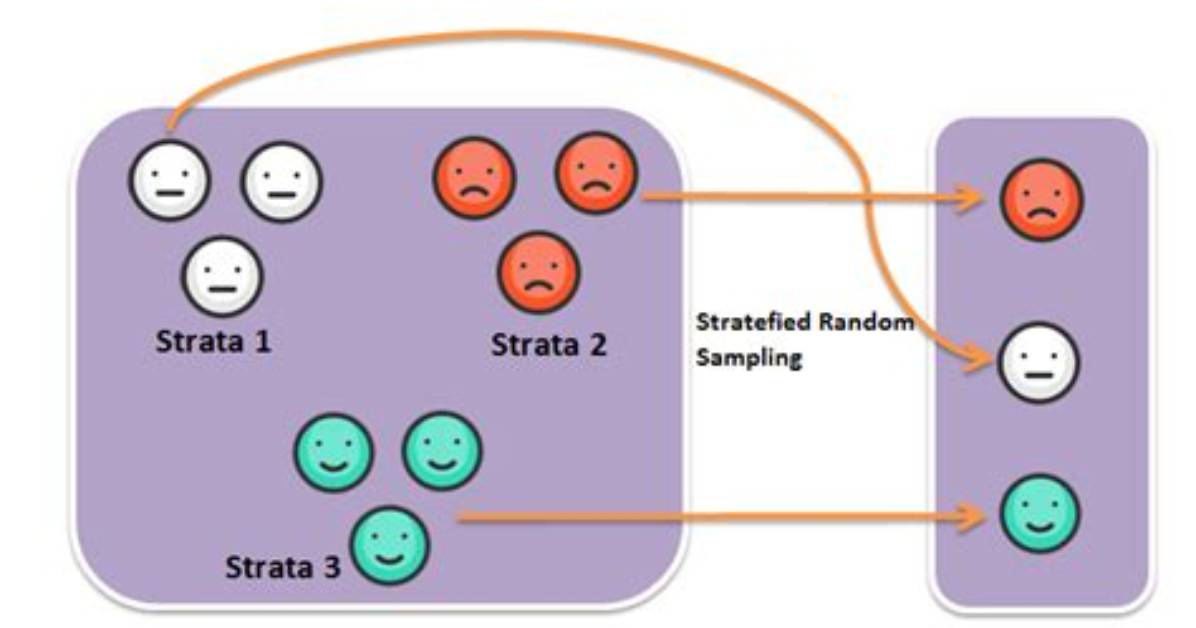
I have a Spark DataFrame that has one column that has lots of zeros and very few ones (only 0.01% of ones).
I'd like to take a random subsample but a stratified one - so that it keeps the ratio of 1s to 0s in that column.
Is it possible to do in pyspark ?
I am looking for a non-scala solution and on based on DataFrames and not RDD-based.
5 Answers
The solution I suggested in Stratified sampling in Spark is pretty straightforward to convert from Scala to Python (or even to Java - What's the easiest way to stratify a Spark Dataset ?).
Nevertheless, I'll rewrite it python. Let's start first by creating a toy DataFrame :
from pyspark.sql.functions import lit
list = [(2147481832,23355149,1),(2147481832,973010692,1),(2147481832,2134870842,1),(2147481832,541023347,1),(2147481832,1682206630,1),(2147481832,1138211459,1),(2147481832,852202566,1),(2147481832,201375938,1),(2147481832,486538879,1),(2147481832,919187908,1),(214748183,919187908,1),(214748183,91187908,1)]
df = spark.createDataFrame(list, ["x1","x2","x3"])
df.show()
# +----------+----------+---+
# |        x1|        x2| x3|
# +----------+----------+---+
# |2147481832|  23355149|  1|
# |2147481832| 973010692|  1|
# |2147481832|2134870842|  1|
# |2147481832| 541023347|  1|
# |2147481832|1682206630|  1|
# |2147481832|1138211459|  1|
# |2147481832| 852202566|  1|
# |2147481832| 201375938|  1|
# |2147481832| 486538879|  1|
# |2147481832| 919187908|  1|
# | 214748183| 919187908|  1|
# | 214748183|  91187908|  1|
# +----------+----------+---+
This DataFrame has 12 elements as you can see :
df.count()
# 12
Distributed as followed :
df.groupBy("x1").count().show()
# +----------+-----+
# |        x1|count|
# +----------+-----+
# |2147481832|   10|
# | 214748183|    2|
# +----------+-----+
Now let's sample :
First we'll set the seed :
seed = 12
The find the keys to fraction on and sample :
fractions = df.select("x1").distinct().withColumn("fraction", lit(0.8)).rdd.collectAsMap()
print(fractions)
# {2147481832: 0.8, 214748183: 0.8}
sampled_df = df.stat.sampleBy("x1", fractions, seed)
sampled_df.show()
# +----------+---------+---+
# |        x1|       x2| x3|
# +----------+---------+---+
# |2147481832| 23355149|  1|
# |2147481832|973010692|  1|
# |2147481832|541023347|  1|
# |2147481832|852202566|  1|
# |2147481832|201375938|  1|
# |2147481832|486538879|  1|
# |2147481832|919187908|  1|
# | 214748183|919187908|  1|
# | 214748183| 91187908|  1|
# +----------+---------+---+
We can now check the content of our sample :
sampled_df.count()
# 9

sampled_df.groupBy("x1").count().show()
# +----------+-----+
# |        x1|count|
# +----------+-----+
# |2147481832|    7|
# | 214748183|    2|
# +----------+-----+
Assume you have titanic dataset in 'data' dataframe which you want to split into train and test set using stratified sampling based on the 'Survived' target variable.
  # Check initial distributions of 0's and 1's
-> data.groupBy("Survived").count().show()

 Survived|count|
 +--------+-----+
 |       1|  342|
 |       0|  549


  # Taking 70% of both 0's and 1's into training set
-> train = data.sampleBy("Survived", fractions={0: 0.7, 1: 0.7}, seed=10)

  # Subtracting 'train' from original 'data' to get test set
-> test = data.subtract(train)


  # Checking distributions of 0's and 1's in train and test sets after the sampling
-> train.groupBy("Survived").count().show()
+--------+-----+
|Survived|count|
+--------+-----+
|       1|  239|
|       0|  399|
+--------+-----+
-> test.groupBy("Survived").count().show()

+--------+-----+
|Survived|count|
+--------+-----+
|       1|  103|
|       0|  150|
+--------+-----+
This can be accomplished pretty easily with 'randomSplit' and 'union' in PySpark.
# read in data
df = spark.read.csv(file, header=True)
# split dataframes between 0s and 1s
zeros = df.filter(df["Target"]==0)
ones = df.filter(df["Target"]==1)
# split datasets into training and testing
train0, test0 = zeros.randomSplit([0.8,0.2], seed=1234)
train1, test1 = ones.randomSplit([0.8,0.2], seed=1234)
# stack datasets back together
train = train0.union(train1)
test = test0.union(test1)
this is based on the accepted answer of @eliasah and this so thread
If you want to get back a train and testset you can use the following function:
from pyspark.sql import functions as F

def stratified_split_train_test(df, frac, label, join_on, seed=42):
    """ stratfied split of a dataframe in train and test set.
    inspiration gotten from:

    """
    fractions = df.select(label).distinct().withColumn("fraction", F.lit(frac)).rdd.collectAsMap()
    df_frac = df.stat.sampleBy(label, fractions, seed)
    df_remaining = df.join(df_frac, on=join_on, how="left_anti")
    return df_frac, df_remaining
to create a stratified train and test set where 80% of the total is used for the training set
df_train, df_test = stratified_split_train_test(df=df, frac=0.8, label="y", join_on="unique_id")
You can use the below function. I used the other answers to combine.
import pyspark.sql.functions as f
from pyspark.sql import DataFrame as SparkDataFrame


def train_test_split_pyspark(
    df: SparkDataFrame,
    startify_column: str,
    unique_col: str = None,
    train_fraction: float = 0.05,
    validation_fraction: float = 0.005,
    test_fraction: float = 0.005,
    seed: int = 1234,
    to_pandas: bool = True,
):
    if not unique_col:
        unique_col = "any_unique_name_here"
        df = df.withColumn(unique_col, f.monotonically_increasing_id())

    # Train data
    train_fraction_dict = (
        df.select(startify_column)
        .distinct()
        .withColumn("fraction", f.lit(train_fraction))
        .rdd.collectAsMap()
    )
    df_train = df.stat.sampleBy(startify_column, train_fraction_dict, seed)
    df_remaining = df.join(df_train, on=unique_col, how="left_anti")

    # Validation data
    validation_fraction_dict = {
        key: validation_fraction for (_, key) in enumerate(train_fraction_dict)
    }
    df_val = df_remaining.stat.sampleBy(startify_column, validation_fraction_dict, seed)
    df_remaining = df_remaining.join(df_val, on=unique_col, how="left_anti")

    # Test data
    test_fraction_dict = {
        key: test_fraction for (_, key) in enumerate(train_fraction_dict)
    }
    df_test = df_remaining.stat.sampleBy(startify_column, test_fraction_dict, seed)

    if unique_col == "any_unique_name_here":
        df_train = df_train.drop(unique_col)
        df_val = df_val.drop(unique_col)
        df_test = df_test.drop(unique_col)

    if to_pandas:
        return (df_train.toPandas(), df_val.toPandas(), df_test.toPandas())
    return df_train, df_val, df_test
Sophia analyzes international trade, startup ecosystems, retail transformation, and supply chain logistics for modern digital publications.
