
Utf-8 Encoded Characters

Utf-8 Supports Any Unicode Character, Which Pragmatically Means Any Natural Language (Coptic, Sinhala, Phonecian, Cherokee Etc), as Well as Many Non-Spoken...
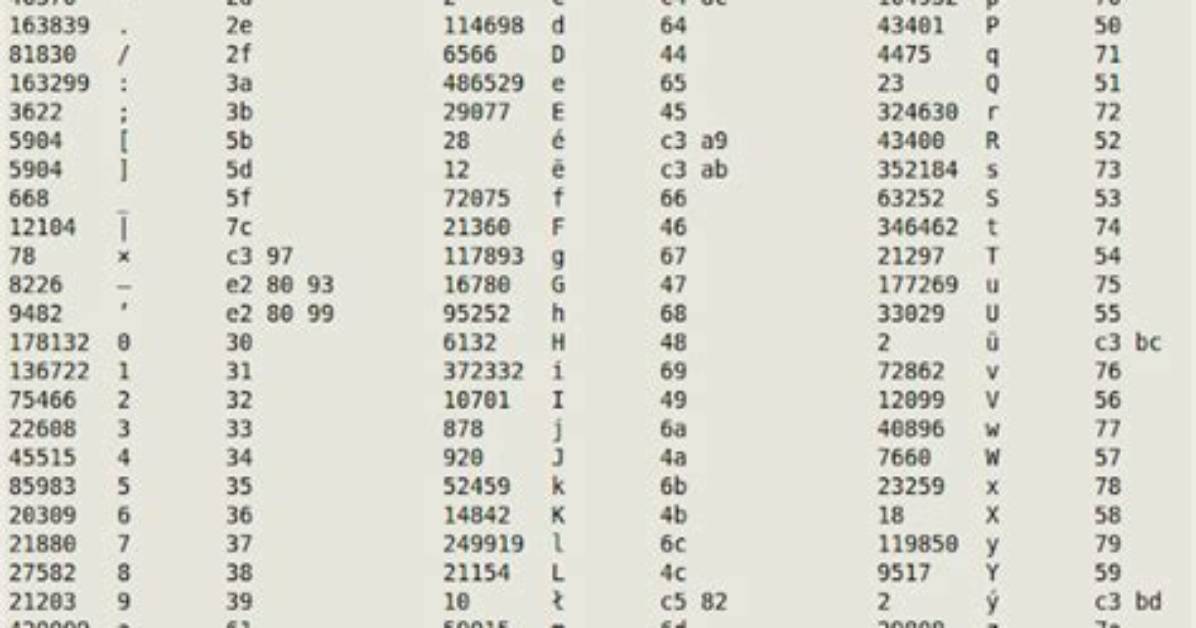
UTF-8 supports any unicode character, which pragmatically means any natural language (Coptic, Sinhala, Phonecian, Cherokee etc), as well as many non-spoken languages (Music notation, mathematical symbols, APL). The stated objective of the Unicode consortium is to encompass all communications.
How do I make UTF-8 encoded?
If you’re still having encoding issues, you can try these steps:
Find the file.Right click on the file | click Open With.Click Notepad.Click File | then Save As.Navigate to the folder where you want to save your file.Provide a name for your file.Add . Make sure that the encoding is set to UTF-8.
Which characters are not supported by UTF-8?
0xC0, 0xC1, 0xF5, 0xF6, 0xF7, 0xF8, 0xF9, 0xFA, 0xFB, 0xFC, 0xFD, 0xFE, 0xFF are invalid UTF-8 code units. A UTF-8 code unit is 8 bits. If by char you mean an 8-bit byte, then the invalid UTF-8 code units would be char values that do not appear in UTF-8 encoded text.
Can UTF-8 handle Chinese characters?
2 Answers. Show activity on this post. UTF-8 and UTF-16 encode exactly the same set of characters. It’s not that UTF-8 doesn’t cover Chinese characters and UTF-16 does.
Are Chinese characters UTF-8?
UTF8 implements unicode, and in unicode, each character has a codepoint, that is between 0x4E00 and 0x9FFF (2 bytes) for all chinese characters. But UTF8 doesn’t encode characters by just storing their codepoint (UTF32 does that).
Does UTF-8 include accents?
UTF-8 is a standard for representing Unicode numbers in computer files. Symbols with a Unicode number from 0 to 127 are represented exactly the same as in ASCII, using one 8-bit byte. This includes all Latin alphabet letters without accents.
Which of these is the correct way to specify a character set of UTF-8 for a HTML file?
Specify the character encoding for the HTML document:
What is not UTF-8 encoded?
This error is created when the uploaded file is not in a UTF-8 format. UTF-8 is the dominant character encoding format on the World Wide Web. This error occurs because the software you are using saves the file in a different type of encoding, such as ISO-8859, instead of UTF-8.
How is Unicode encoded?
Unicode uses two encoding forms: 8-bit and 16-bit, based on the data type of the data that is being that is being encoded. The default encoding form is 16-bit, where each character is 16 bits (2 bytes) wide. Sixteen-bit encoding form is usually shown as U+hhhh, where hhhh is the hexadecimal code point of the character.
How do you know if a file is UTF-8 encoded?
Open the file in Notepad. Click ‘Save As’. In the ‘Encoding:’ combo box you will see the current file format. Yes, I opened the file in notepad and selected the UTF-8 format and saved it.
What encoding to use for French characters?
French Characters in HTML Documents – ISO-8859-1 Encoding.
Why did UTF-8 replace the ASCII character and coding standard?
Why did UTF-8 replace the ASCII character-encoding standard? UTF-8 can store a character in more than one byte. UTF-8 replaced the ASCII character-encoding standard because it can store a character in more than a single byte. This allowed us to represent a lot more character types, like emoji.
What are the limitations of the 8-bit Extended Ascii character set How can these limitations be overcome?
Limitation of ASCII
The 128 or 256 character limits of ASCII and Extended ASCII limits the number of character sets that can be held. Representing the character sets for several different language structures is not possible in ASCII, there are just not enough available characters.
Does UTF-8 support Russian?
Cyrillic can be represented on a Linux computer by four main methods: KOI8-R, ISO 8859-5, Windows 1251 Codepage, and ISO 10646-1 UTF-8 Unicode 3.0.
Does UTF-8 support Arabic?
The most common Unicode encodings are UTF-8 and UTF-16. To summarise: ISO 8859-6 uses 1 byte for each Arabic character, but doesn’t support “Arabic presentation forms”, nor characters from any other script than ASCII. UTF-8 uses 2 bytes for each Arabic character, and 3 bytes for “Arabic presentation forms”.
Does UTF-8 support Japan?
The Unicode Standard supports all of the CJK characters from JIS X 0208, JIS X 0212, JIS X 0221, or JIS X 0213, for example, and many more. This is true no matter which encoding form of Unicode is used: UTF-8, UTF-16, or UTF-32.
Postos Recomendados
welche komponenten sind im pc verbaut ueberpruefen sie es was ist in meinem pc verbaut
shrek 2 cena os melhores filmes hd gratis os ultimos videos online que voce nao deve perder em 2021 2022
raya eo ultimo dragao ultimos videos filmes hd que vale a pena assistir em 2021
de perto ela nao e normal netflix filmes hd ultimos videos que vale a pena assistir em 2021 2022
filme de acao gratis online os melhores filmes hd gratis os ultimos videos online que voce nao deve perder em 2021 2022
faxina os melhores filmes hd gratis os ultimos videos online que voce nao deve perder em 2021 2022
bandeira da coreia do sul os melhores videos online que voce deve assistir em 2021 2022
melhores comedias romanticas da netflix os melhores filmes hd gratis os ultimos videos online que voce nao deve perder em 2021 2022
Robert Thorne covers electric vehicle innovations, autonomous driving systems, global mobility trends, and automotive engineering developments.
