
Webscraping a Table from Vegasinsider

I'd Like to Scrape This Table from Vegas Insider I Am a Total Beginner When It Comes to Web Scraping. I Have Tried a Few Different Ways via Stackoverflow but...
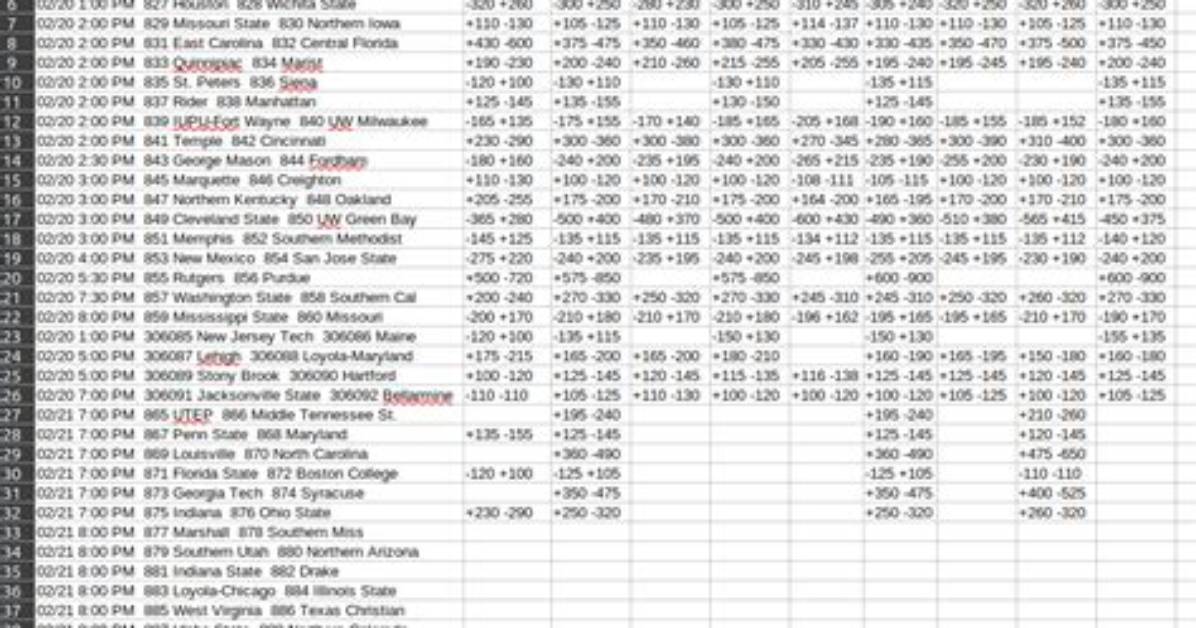
I'd like to scrape this table from Vegas Insider
I am a total beginner when it comes to web scraping. I have tried a few different ways via stackoverflow but haven't been able to nail it down.
This is as far as I have been able to get.
from bs4 import BeautifulSoup
import requests

source = requests.get(').text

soup = BeautifulSoup(source, "html.parser")
tbl = soup.find('table', class_='frodds-data-tbl')
for matchups in tbl.find_all('td', {'class': ['viCellBg1', 'oddsGameCell','cellTextNorm','cellTextNorm']}):
    if matchups.span is not None:
        gameDate = matchups.span.text
        print(gameDate)

    for b_ in matchups.find_all('b'):
        print(b_.a.text)
I'd eventually send these results to a CSV and change the column headers to match the book names on the table. Any help here is appreciated.
2 Answers
You can use this example how to load the data into a DataFrame:
import requests
import pandas as pd
from bs4 import BeautifulSoup

url = ""
soup = BeautifulSoup(requests.get(url).content, "html.parser")

# clean-up the cells:
for br in soup.select("br"):
    br.replace_with("\n")

df = pd.read_html(str(soup.select_one(".frodds-data-tbl")))[0]

# set column names:
# df.columns = ['col1', 'col2', ...]

df.to_csv("data.csv", index=False)
print(df)
Prints:
                                                              0           1          2          3          4          5          6          7          8          9
0            02/20 1:00 PM  819 Wright State  820 Detroit Mercy   -120 +100  -125 +105  -125 +105  -120 +100  -114 -105  -115 -105  -120 +100  -120 +100  -125 +105
1                    02/20 1:00 PM  821 Michigan  822 Wisconsin   +110 -130  +135 -155  +125 -150  +135 -155  +130 -156  +130 -150  +135 -160  +120 -145  +135 -155
2                     02/20 1:00 PM  823 Providence  824 Butler   -160 +130  -155 +135  -170 +140  -160 +140  -170 +140  -160 +140  -160 +135  -155 +127  -155 +135
3                        02/20 1:00 PM  825 Fairfield  826 Iona  +650 -1000  +525 -750  +550 -800  +525 -750  +520 -780  +500 -720  +530 -750  +600 -900  +500 -700

...
and saves data.csv (screenshot from LibreOffice):
If you don't care about the formatting, you can use pd.read_html:
import pandas as pd
url = ""
pd.read_html(url)[7]
Marcus Vance is a cybersecurity auditor and technology writer dedicated to educating the public about online safety, data privacy regulations, enterprise security, and emerging cyber threats.
