
What Clustering in Data Mining?

Clustering in Data Mining. Clustering Is an Unsupervised Machine Learning-Based Algorithm That Comprises a Group of Data Points into Clusters So That the...
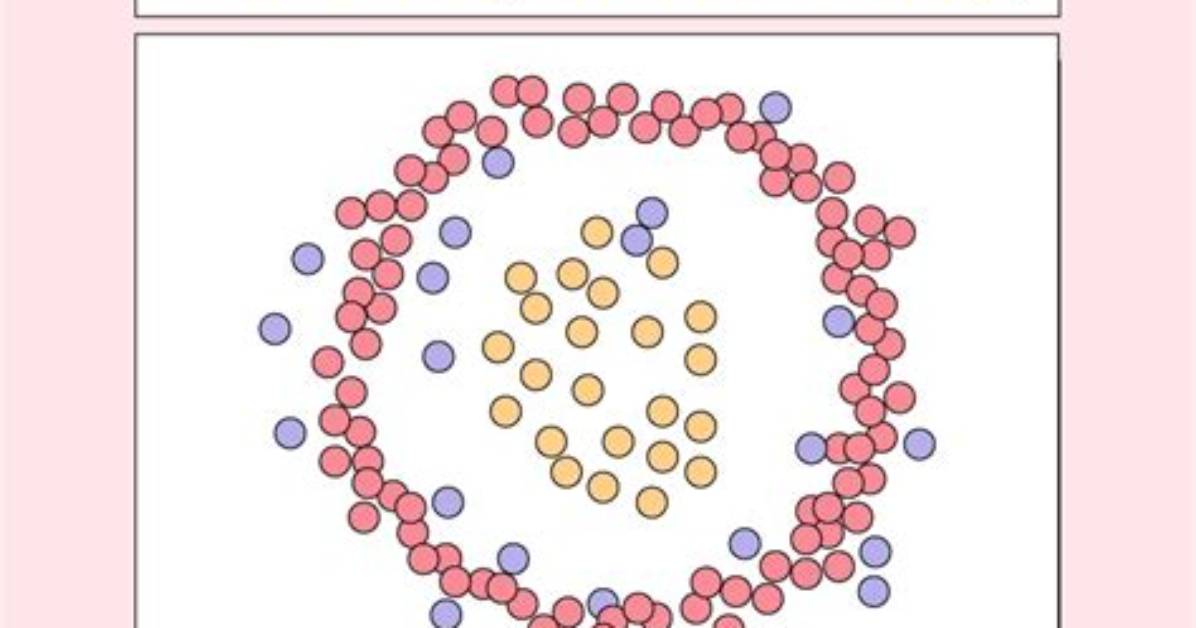
Clustering in Data Mining. Clustering is an unsupervised Machine Learning-based Algorithm that comprises a group of data points into clusters so that the objects belong to the same group. ... Each of these subsets contains data similar to each other, and these subsets are called clusters.
What is clustering in data mining with example?
In clustering, a group of different data objects is classified as similar objects. ... After the classification of data into various groups, a label is assigned to the group. It helps in adapting to the changes by doing the classification. Read: Common Examples of Data Mining.
What is meant by data clustering?
Clustering is the task of dividing the population or data points into a number of groups such that data points in the same groups are more similar to other data points in the same group than those in other groups. In simple words, the aim is to segregate groups with similar traits and assign them into clusters.
David Miller brings 15 years of experience in global economics, personal finance strategy, and market dynamics. He specializes in turning complex economic trends into actionable insights for everyday readers.
