
What Programming Paradigm Is Hadoop Mapreduce Based on?

Mapreduce Is a Processing Technique and a Program Model for Distributed Computing Based on Java. the Mapreduce Algorithm Contains Two Important Tasks, Namely...
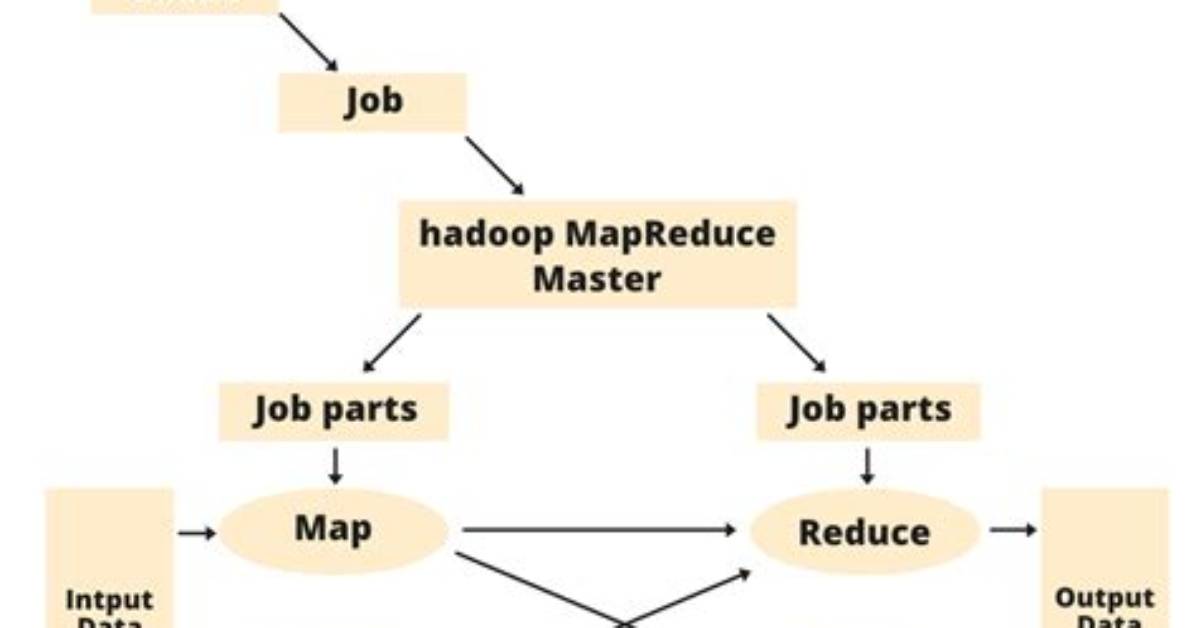
.
Herein, what is MapReduce and how it works in Hadoop?
Apache Hadoop MapReduce is a framework for processing large data sets in parallel across a Hadoop cluster. Data analysis uses a two step map and reduce process. The job configuration supplies map and reduce analysis functions and the Hadoop framework provides the scheduling, distribution, and parallelization services.
Subsequently, question is, what is MapReduce paradigm? MapReduce is a programming paradigm that was designed to allow parallel distributed processing of large sets of data, converting them to sets of tuples, and then combining and reducing those tuples into smaller sets of tuples.
Likewise, people ask, what is MapReduce in Hadoop with example?
MapReduce is a programming framework that allows us to perform distributed and parallel processing on large data sets in a distributed environment. Then, the reducer aggregates those intermediate data tuples (intermediate key-value pair) into a smaller set of tuples or key-value pairs which is the final output.
How do I run a MapReduce program in Hadoop?
Running the WordCount Example in Hadoop MapReduce using Java Project with Eclipse
- Step 1 – Let's create the java project with the name “Sample WordCount” as shown below -
- Step 2 - The next step is to get references to hadoop libraries by clicking on Add JARS as follows –
- Step 3 -
- Step 4 –
- Step 5 -
