
You Asked: How Do I Remove Duplicate Lines in Linux?

Contents the Uniq Command Is Used to Remove Duplicate Lines from a Text File in Linux. by Default, This Command Discards All but the First of Adjacent Repeated...
The uniq command is used to remove duplicate lines from a text file in Linux. By default, this command discards all but the first of adjacent repeated lines, so that no output lines are repeated. Optionally, it can instead only print duplicate lines. For uniq to work, you must first sort the output.
How do I remove duplicates in Unix?
uniq command retains only unique records from a file. In other words, uniq removes duplicates. However, uniq command needs a sorted file as input. sort with -u option removes all the duplicate records and hence uniq is not needed at all.
Must Read
How do I get rid of duplicate lines?
Remove duplicate values
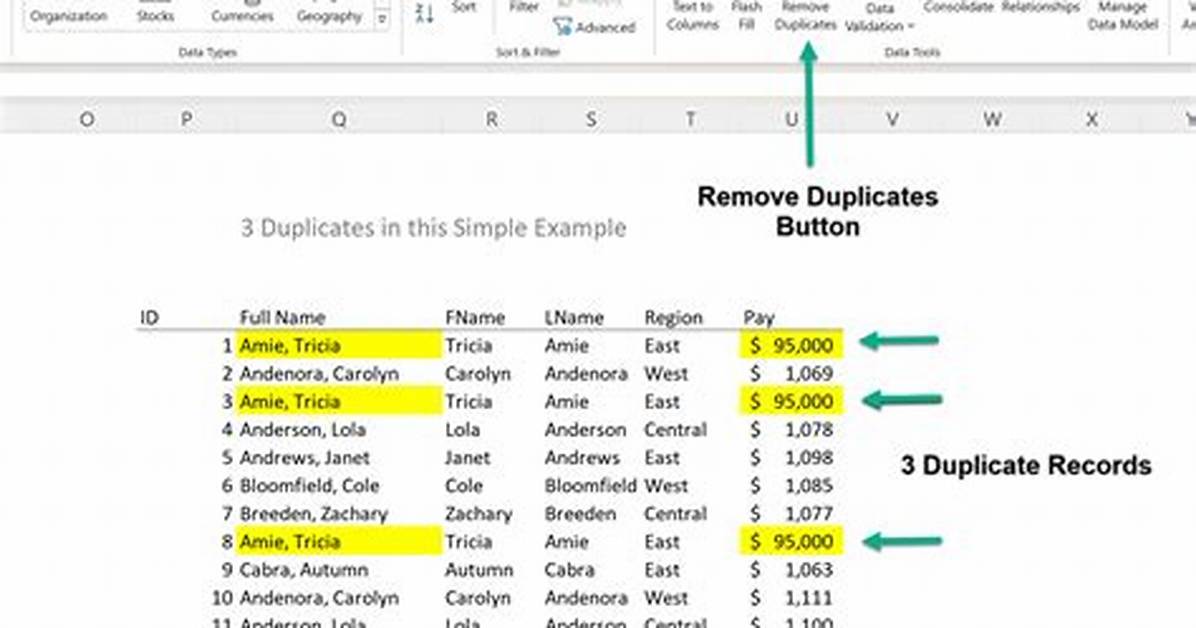
- Select the range of cells that has duplicate values you want to remove. Tip: Remove any outlines or subtotals from your data before trying to remove duplicates.
- Click Data > Remove Duplicates, and then Under Columns, check or uncheck the columns where you want to remove the duplicates. …
- Click OK.
Sophia analyzes international trade, startup ecosystems, retail transformation, and supply chain logistics for modern digital publications.
